Hypothesis, Meaning, Nature, Significance, Types, Null Hypothesis & Alternative Hypothesis

Hypothesis is a proposed explanation or assumption made on the basis of limited evidence, serving as a starting point for further investigation. In research, it acts as a predictive statement that can be tested through study and experimentation. A good hypothesis clearly defines the relationship between variables and provides direction to the research process. It can be formulated as a positive assertion, a negative assertion, or a question. Hypotheses help researchers focus their study, collect relevant data, and analyze outcomes systematically. If supported by evidence, a hypothesis strengthens theories; if rejected, it helps refine or redirect the research.

Nature of Hypothesis

  • Predictive Nature

A hypothesis predicts the possible outcome of a research study. It forecasts the relationship between two or more variables based on prior knowledge, observations, or theories. Through prediction, the researcher sets a direction for investigation and frames experiments accordingly. The predictive nature helps in formulating tests and procedures that validate or invalidate the assumptions. By predicting outcomes, a hypothesis serves as a guiding tool for collecting and analyzing data systematically in the research process.

  • Testable and Verifiable

A fundamental nature of a hypothesis is that it must be testable and verifiable. Researchers should be able to design experiments or collect data to prove or disprove the hypothesis objectively. If a hypothesis cannot be tested or verified with empirical evidence, it has no scientific value. Testability ensures that the hypothesis remains grounded in reality and allows researchers to apply statistical tools, experiments, or observations to validate the proposed relationships or statements.

  • Simple and Clear

A good hypothesis must be simple, clear, and understandable. It should not be complex or vague, as this makes testing and interpretation difficult. The clarity of a hypothesis allows researchers and readers to grasp its meaning without confusion. It should specifically state the expected relationship between variables and avoid unnecessary technical jargon. A simple hypothesis makes the research process more organized and structured, leading to more reliable and meaningful results during analysis.

  • Specific and Focused

The nature of a hypothesis demands that it be specific and focused on a particular issue or problem. It should not be broad or cover unrelated aspects, which can dilute the research findings. Specificity helps researchers concentrate their efforts on one clear objective, design relevant research methods, and gather precise data. A focused hypothesis reduces ambiguity, minimizes errors, and improves the validity of the research results by maintaining a sharp direction throughout the study.

  • Consistent with Existing Knowledge

A hypothesis should align with the existing body of knowledge and theories unless it aims to challenge or expand them. It should logically fit into the current understanding of the subject to make sense scientifically. When a hypothesis is consistent with known facts, it gains credibility and relevance. Even when proposing something new, a hypothesis should acknowledge previous research and build upon it, rather than ignoring established evidence or scientific frameworks.

  • Objective and Neutral

A hypothesis must be objective and free from personal bias, emotions, or preconceived notions. It should be based on observable facts and logical reasoning rather than personal beliefs. Researchers must frame their hypotheses with neutrality to ensure that the research process remains fair and unbiased. Objectivity enhances the scientific value of the study and ensures that conclusions are drawn based on evidence rather than assumptions, preferences, or subjective interpretations.

  • Tentative and Provisional

A hypothesis is not a confirmed truth but a tentative statement awaiting validation through research. It is subject to change, modification, or rejection based on the findings. Researchers must remain open-minded and willing to revise the hypothesis if new evidence contradicts it. This provisional nature is crucial for the progress of scientific inquiry, as it encourages continuous testing, exploration, and refinement of ideas instead of blindly accepting assumptions.

  • Relational Nature

Hypotheses often establish relationships between two or more variables. They state how one variable may affect, influence, or be associated with another. This relational nature forms the backbone of experimental and correlational research designs. Understanding these relationships helps researchers explain causes, predict effects, and identify patterns within their study areas. Clearly stated relationships in hypotheses also facilitate the application of statistical tests and the interpretation of research findings effectively.

Significance of Hypothesis

  • Guides the Research Process

The hypothesis acts as a roadmap for the researcher, providing clear direction and focus. It helps define what needs to be studied, which variables to observe, and what methods to apply. Without a hypothesis, research would be unguided and scattered. By offering a structured path, it ensures that the research efforts are purposeful and systematically organized toward achieving meaningful outcomes.

  • Defines the Focus of Study

A hypothesis narrows the scope of the study by specifying exactly what the researcher aims to investigate. It identifies key variables and their expected relationships, preventing unnecessary data collection. This concentration saves time and resources while allowing for more detailed analysis. A focused study helps in maintaining clarity throughout the research process and results in stronger, more convincing conclusions based on targeted inquiry.

  • Establishes Relationships Between Variables

A hypothesis highlights the potential relationships between two or more variables. It outlines whether variables move together, influence each other, or remain independent. Establishing these relationships is essential for explaining complex phenomena. Through hypothesis testing, researchers can confirm or reject assumed connections, leading to deeper understanding, better theories, and stronger predictive capabilities in both scientific and business research contexts.

  • Helps in Developing Theories

Hypotheses contribute significantly to theory building. When a hypothesis is repeatedly tested and supported by empirical evidence, it can help form new theories or refine existing ones. Theories built on tested hypotheses have greater scientific value and can guide future research and practice. Thus, hypotheses are not just for individual studies; they play a critical role in expanding the broader knowledge base of a discipline.

  • Facilitates the Testing of Concepts

Concepts and assumptions need validation before they can be widely accepted. A hypothesis facilitates this validation by providing a mechanism for empirical testing. It helps researchers design experiments or surveys specifically aimed at confirming or disproving a particular idea. This ensures that concepts do not remain speculative but are subjected to rigorous scientific scrutiny, enhancing the reliability and acceptance of research findings.

  • Enhances Objectivity in Research

Having a well-defined hypothesis enhances objectivity by setting specific criteria that research must meet. Researchers approach data collection and analysis with a neutral mindset focused on proving or disproving the hypothesis. This objectivity minimizes the influence of personal biases or preconceived notions, promoting fair and unbiased research results. In this way, hypotheses help maintain the scientific integrity of research projects.

  • Assists in Decision Making

In applied fields like business and healthcare, hypotheses help decision-makers by providing data-driven insights. By testing hypotheses about consumer behavior, product performance, or treatment outcomes, organizations and professionals can make informed decisions. This reduces risks and improves strategic planning. A hypothesis, therefore, transforms vague assumptions into evidence-based conclusions that directly impact policies, operations, and practices.

  • Saves Time and Resources

By clearly defining what needs to be studied, a hypothesis prevents researchers from wasting time and resources on irrelevant data. It limits the research to specific objectives and focuses efforts on gathering meaningful, actionable information. Efficient use of resources is critical in both academic and professional research settings, making a well-structured hypothesis an essential tool for maximizing productivity and effectiveness.

Types of Hypothesis

1. Null Hypothesis

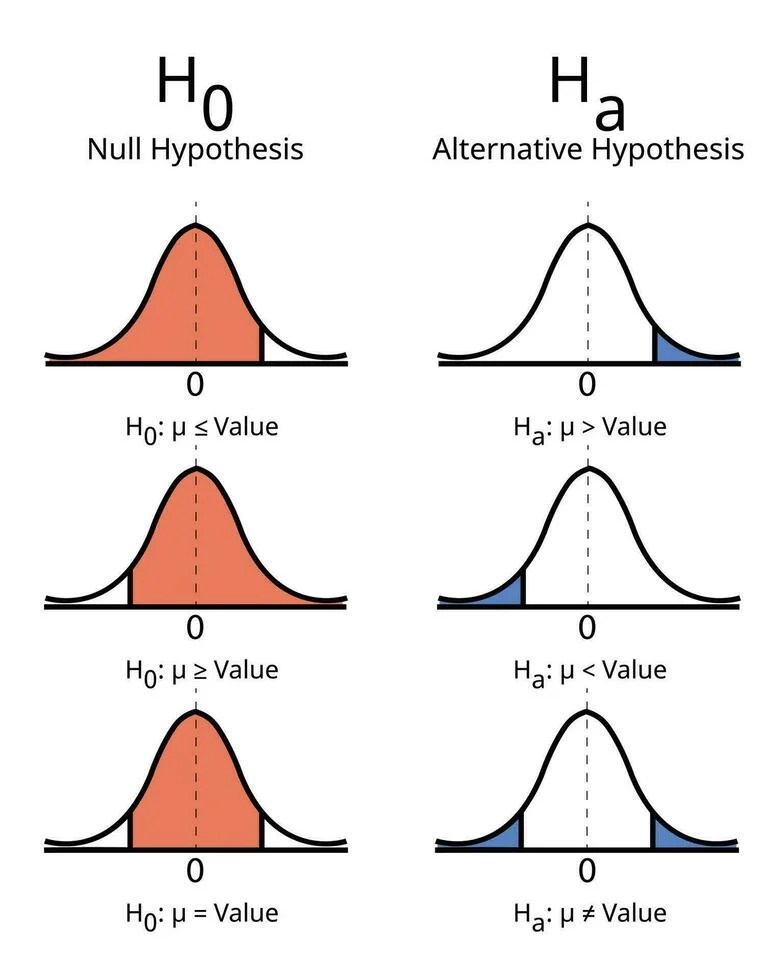
Null Hypothesis (H₀) states that there is no significant relationship, effect, or difference between the variables being studied. It is generally tested statistically to determine whether the observed result could have occurred by chance. For example, a researcher may propose that there is no significant difference in customer satisfaction between two brands. If sufficient statistical evidence is obtained, the null hypothesis may be rejected. It provides a basis for conducting statistical hypothesis testing in business research.

2. Alternative Hypothesis

Alternative Hypothesis (H₁ or Ha) states that a significant relationship, effect, or difference exists between the variables under investigation. It represents the researcher’s proposed explanation or expectation and is considered when the null hypothesis is rejected. For example, a researcher may propose that employee training significantly improves productivity. The alternative hypothesis can be directional or non-directional. It helps researchers investigate whether changes in one variable are associated with changes or differences in another variable.

3. Directional Hypothesis

Directional Hypothesis specifies the expected direction of the relationship between variables. It predicts whether one variable will increase or decrease when another variable changes. Words such as positive, negative, increase, decrease, higher, or lower are commonly used. For example, a researcher may hypothesize that increased advertising expenditure increases sales. Directional hypotheses are generally developed when previous research or established theory provides a reasonable basis for predicting the direction of a relationship.

4. Non-Directional Hypothesis

Non-Directional Hypothesis states that a significant relationship or difference exists between variables but does not specify its direction. It indicates that the variables are associated without predicting whether the relationship will be positive or negative. For example, a researcher may hypothesize that advertising expenditure is significantly related to sales without stating whether sales increase or decrease. This type is useful when previous research provides insufficient evidence to predict the specific direction of the relationship.

5. Simple Hypothesis

Simple Hypothesis involves a relationship between one independent variable and one dependent variable. The independent variable is considered the influencing factor, while the dependent variable represents the outcome being studied. For example, a researcher may examine whether employee training affects employee productivity. Here, employee training is the independent variable and productivity is the dependent variable. Simple hypotheses are relatively easy to formulate, measure, and test, making them useful for studying straightforward relationships in business research.

6. Complex Hypothesis

Complex Hypothesis involves two or more independent variables, dependent variables, or both. It examines relationships among multiple factors within a research problem. For example, a researcher may investigate whether training, motivation, and work environment influence employee productivity. Complex hypotheses are useful when business outcomes are affected by several factors simultaneously. They generally require more advanced data analysis and statistical techniques to examine the relationships and determine the individual or combined effects of different variables.

7. Associative Hypothesis

Associative Hypothesis proposes that two or more variables are related or associated with each other without necessarily stating that one variable causes changes in another. It focuses on identifying the existence and nature of a relationship. For example, a researcher may hypothesize that customer satisfaction is associated with customer loyalty. The research can examine whether changes in one variable correspond with changes in another. Associative hypotheses are commonly used in correlational and descriptive business research.

8. Causal Hypothesis

Causal Hypothesis proposes a cause-and-effect relationship between variables. It suggests that changes in an independent variable produce changes in a dependent variable. For example, a researcher may hypothesize that reducing product prices increases sales volume. Causal hypotheses are often examined through experimental research, controlled studies, or appropriate statistical analysis. They are particularly useful for evaluating business decisions involving pricing, advertising, training, incentives, production methods, and promotional strategies.

Null Hypothesis

The null hypothesis (H₀) is a fundamental concept in statistical testing that proposes no significant relationship or difference exists between variables being studied. It serves as the default position that researchers aim to test against, representing the assumption that any observed effects are due to random chance rather than systematic influences.

In experimental design, the null hypothesis typically states there is:

  • No difference between groups

  • No association between variables

  • No effect of a treatment/intervention

For example, in testing a new drug’s efficacy, H₀ would state “the drug has no effect on symptom reduction compared to placebo.” Researchers then collect data to determine whether sufficient evidence exists to reject this null position in favor of the alternative hypothesis (H₁), which proposes an actual effect exists.

Statistical tests calculate the probability (p-value) of obtaining the observed results if H₀ were true. When this probability falls below a predetermined significance level (usually p < 0.05), researchers reject H₀. Importantly, failing to reject H₀ doesn’t prove its truth – it simply indicates insufficient evidence against it. The null hypothesis framework provides objective criteria for making inferences while controlling for Type I errors (false positives).

Alternative Hypothesis

The alternative hypothesis represents the researcher’s actual prediction about a relationship between variables, contrasting with the null hypothesis. It states that observed effects are real and not due to random chance, proposing either:

  1. A significant difference between groups

  2. A measurable association between variables

  3. A true effect of an intervention

Unlike the null hypothesis’s conservative stance, the alternative hypothesis embodies the research’s theoretical expectations. In a clinical trial, while H₀ states “Drug X has no effect,” H₁ might claim “Drug X reduces symptoms by at least 20%.”

Alternative hypotheses can be:

  • Directional (one-tailed): Predicting the specific nature of an effect (e.g., “Group A will score higher than Group B”)

  • Non-directional (two-tailed): Simply stating a difference exists without specifying direction

Statistical testing doesn’t directly prove H₁; rather, it assesses whether evidence sufficiently contradicts H₀ to support the alternative. When results show statistical significance (typically p < 0.05), we reject H₀ in favor of H₁.

The alternative hypothesis drives research design by determining appropriate statistical tests, required sample sizes, and measurement precision. It must be formulated before data collection to prevent post-hoc reasoning. Well-constructed alternative hypotheses are testable, falsifiable, and grounded in theoretical frameworks, providing the foundation for meaningful scientific conclusions.
Decision Support System, Evolution, Objectives, Working, Types, Limitations

Decision Support System (DSS) is an interactive, computer-based system that assists managers and decision-makers in solving semi-structured and unstructured problems by combining data, analytical models, and user judgment. Unlike TPS or MIS, which handle routine reporting, DSS provides analytical tools, simulations, and “what-if” scenario analysis to support complex decision-making. It draws data from internal sources (like TPS/MIS) and external sources (market trends, competitor data) to generate customized insights. DSS is typically used at the management and strategic levels, helping evaluate alternatives and predict outcomes before committing resources. Examples include financial planning systems, forecasting tools, and resource allocation models used across various industries.

Evolution of Decision Support System:

1. Early Development: 1960s

The concept of Decision Support Systems (DSS) began developing during the 1960s with advances in computers and management science. Organisations started using computers to process large amounts of business data and perform mathematical calculations. Early systems mainly supported structured decisions through management science models, statistical analysis, and operational research techniques. Computers were primarily used for data processing rather than interactive decision making. Researchers began exploring ways to combine computer technology with managerial judgement. This period established the foundation for DSS by demonstrating that computer based models could help managers analyse business problems and evaluate different alternatives more effectively.

2. Development of Management Information Systems: 1970s

During the 1970s, Management Information Systems (MIS) became widely used for providing managers with regular reports and business information. However, traditional MIS mainly supported structured and routine decisions. The need for systems that could assist managers with semi structured and non routine decisions encouraged the development of DSS. Researchers began combining databases with analytical models to create more interactive systems. Managers could use these systems to examine information, change assumptions, and evaluate alternatives. This period marked an important shift from simple reporting towards interactive computer based decision support for managerial problem solving.

3. Interactive DSS: 1980s

During the 1980s, DSS became more interactive and accessible because of improvements in personal computers, database technology, and user friendly software. Managers could directly interact with systems rather than depending entirely on technical specialists. Spreadsheet programs became particularly useful for financial analysis, forecasting, budgeting, and what if analysis. DSS began incorporating tools for modelling, simulation, forecasting, and sensitivity analysis. Organisations increasingly used these systems for strategic and tactical decisions. The development of graphical interfaces also made information easier to understand. As a result, DSS became a practical tool for managers in various business functions.

4. Group Decision Support Systems: 1990s

During the 1990s, DSS expanded with the development of Group Decision Support Systems (GDSS) and network technologies. These systems were designed to support decision making by groups rather than individual managers. GDSS provided tools for communication, information sharing, brainstorming, voting, and evaluation of alternatives. The growth of the Internet, data warehouses, and enterprise systems also increased the availability of organisational information. DSS could integrate information from multiple departments and external sources. This period strengthened collaborative decision making and enabled managers located in different places to work together using computer based decision support tools.

5. Modern DSS: 2000s Onwards

From the 2000s onwards, DSS evolved significantly through business intelligence, big data, cloud computing, artificial intelligence, and machine learning. Modern DSS can process large volumes of structured and unstructured data from multiple sources. Advanced analytics helps organisations identify patterns, forecast trends, and evaluate possible outcomes. Cloud based DSS allows users to access information from different locations and devices. Artificial intelligence can provide recommendations and predictive insights while managers retain decision making responsibility. Today, DSS is used in areas such as finance, marketing, healthcare, supply chain management, and human resources, supporting faster and more data driven decisions.

Objectives of Decision Support System:

1. Supporting Managerial Decision Making

The primary objective of a Decision Support System (DSS) is to assist managers in making effective decisions. It provides relevant data, analytical tools, and models that help managers understand different aspects of a problem. DSS is particularly useful for semi structured and non routine decisions where human judgement is required. It does not replace managers but provides information and analysis to support their judgement. Managers can examine different alternatives and select an appropriate course of action. Thus, DSS helps improve the quality, speed, and reliability of managerial decisions while reducing uncertainty associated with complex business situations.

2. Improving Decision Quality

DSS aims to improve the quality and accuracy of decisions by providing managers with relevant and reliable information. It allows users to analyse data, identify relationships, compare alternatives, and evaluate possible outcomes. Tools such as forecasting, simulation, and sensitivity analysis help managers understand the potential effects of different decisions. By using systematic analysis rather than relying only on intuition, managers can make better informed choices. DSS also helps identify important trends and exceptions that may not be immediately visible. Therefore, improving the quality of managerial decisions is a major objective of implementing a Decision Support System.

3. Analysing Alternatives

An important objective of DSS is to help managers identify, compare, and evaluate alternative solutions to a business problem. The system allows users to change assumptions and examine different possible outcomes. Techniques such as what if analysis, sensitivity analysis, and scenario analysis are commonly used for this purpose. For example, a manager can analyse how changes in price, costs, or demand may affect profits. This helps managers understand the advantages and possible consequences of different choices. By providing systematic comparison of alternatives, DSS supports managers in selecting solutions that are appropriate for the situation and organisational objectives.

4. Handling Complex Problems

DSS is designed to assist managers in dealing with complex and non routine problems that cannot be solved effectively through standard procedures. Such problems may involve uncertain information, multiple variables, and several possible solutions. DSS uses databases, analytical models, forecasting techniques, and simulations to examine these problems. Managers can combine system generated analysis with their own experience and judgement. For example, DSS can help analyse complex decisions related to investment, resource allocation, production planning, and market expansion. Therefore, DSS helps managers understand complicated situations and provides a structured approach for analysing problems and developing suitable solutions.

5. Reducing Uncertainty

Another important objective of DSS is to reduce uncertainty in managerial decision making. Business decisions are often affected by changing market conditions, customer behaviour, costs, competition, and other unpredictable factors. DSS provides historical data, current information, forecasts, and analytical models that help managers understand these factors. Scenario analysis and forecasting can show how different conditions may affect future results. Although DSS cannot completely eliminate uncertainty, it helps managers assess possible outcomes and risks more systematically. Thus, DSS provides a stronger information base and enables managers to make decisions with greater awareness of potential risks and consequences.

6. Increasing Decision Making Efficiency

DSS aims to make the decision making process faster and more efficient. It provides managers with quick access to relevant information and analytical tools, reducing the time required to collect and analyse data manually. Managers can generate reports, perform calculations, compare alternatives, and examine scenarios through an integrated system. This is particularly useful when decisions must be made within a limited time. DSS also reduces repetitive analytical work and allows managers to focus on interpreting results and applying their judgement. Therefore, it improves the speed, convenience, and efficiency of the managerial decision making process.

Working of Decision Support System:

1. Data Collection

The first stage in the working of a Decision Support System (DSS) is collecting relevant data from different sources. Data may be obtained from internal sources such as sales records, financial statements, inventory records, and employee information, as well as external sources such as market reports, economic data, and competitor information. The collected data may be historical or current. DSS brings this information together so that managers can analyse a particular business problem. Accurate and relevant data is important because the quality of the information directly affects the quality of the analysis and decisions produced by the system.

2. Data Storage and Management

After collection, data is stored and organised in databases so that it can be easily accessed when required. The DSS database may contain information related to sales, customers, costs, production, finance, markets, and other business activities. Data management tools help in organising, updating, and retrieving information efficiently. The system may also integrate information from multiple internal and external sources. Proper data storage ensures that managers have access to consistent and relevant information. A well organised database forms an important foundation of DSS because analytical models and decision making tools depend on reliable data.

3. Model Processing

The model base is an important component of DSS that applies mathematical, statistical, financial, or analytical models to available data. It helps managers examine business problems and evaluate possible solutions. Common techniques include forecasting, simulation, optimisation, what if analysis, and sensitivity analysis. For example, a manager can use a forecasting model to estimate future sales or a financial model to analyse investment alternatives. The system processes the selected data through appropriate models and produces analytical results. This stage converts raw business information into useful insights that can help managers understand problems and evaluate different courses of action.

4. User Interaction

DSS provides an interactive interface through which managers can communicate with the system and control the analysis. Users can enter assumptions, select data, change variables, choose analytical models, and request reports or visualisations. The system responds to these inputs and presents the results in an understandable form. Managers can perform repeated analysis by changing different conditions and observing their effects. This interactive nature distinguishes DSS from systems that only provide fixed reports. It allows managers to combine computer based analysis with their own knowledge, experience, and judgement while examining complex business situations.

5. Evaluation of Alternatives

After processing the data, DSS helps managers identify and evaluate different alternatives. The system may compare possible solutions based on factors such as cost, revenue, risk, resources, or expected performance. Managers can use techniques such as scenario analysis and what if analysis to understand how changes in assumptions may affect results. The system presents the consequences of different choices, allowing managers to examine their potential benefits and limitations. DSS does not normally make the final decision itself. Instead, it provides analytical support that enables managers to understand alternatives and apply their professional judgement.

6. Decision and Feedback

The final stage involves using the information and analysis provided by DSS to support managerial decision making. After evaluating alternatives, the manager selects an appropriate course of action based on organisational objectives and available information. The decision may involve areas such as pricing, investment, production, marketing, or resource allocation. After implementation, actual results can be collected and compared with expected outcomes. This feedback can be used to update the database and improve future analysis. Therefore, DSS supports a continuous decision making process, where data, analysis, managerial judgement, action, and feedback work together to improve organisational performance.

Types of Decision Support System:

1. Data Driven Decision Support System

A Data Driven Decision Support System focuses mainly on analysing large amounts of data to support managerial decisions. It collects information from databases, data warehouses, transaction systems, and external sources. Managers can use the system to identify trends, patterns, relationships, and exceptions in business data. It commonly provides reports, dashboards, data visualisation, and analytical queries. For example, a retail company can analyse historical sales data to identify high performing products and customer buying patterns. Data driven DSS is widely used in sales analysis, financial analysis, inventory management, and marketing to support informed and evidence based decisions.

2. Model Driven Decision Support System

A Model Driven Decision Support System uses mathematical, statistical, financial, or simulation models to analyse business problems. Instead of relying only on historical data, it helps managers understand the possible effects of different decisions. Common techniques include forecasting, optimisation, simulation, and what if analysis. For example, a production manager can use a model to determine the most suitable production level based on available resources and expected demand. Model driven DSS is useful for complex decisions involving multiple variables and alternatives. It helps managers evaluate possible outcomes and select suitable solutions using systematic analytical methods.

3. Knowledge Driven Decision Support System

A Knowledge Driven Decision Support System uses stored knowledge, rules, and expert information to provide recommendations or solutions to users. It may use expert systems, artificial intelligence, and rule based techniques to analyse a problem and suggest appropriate actions. The system uses knowledge obtained from experts, previous cases, organisational procedures, and specialised databases. For example, a knowledge driven DSS can help a financial institution identify potentially risky loan applications based on predefined rules. It is useful when specialised knowledge is required for decision making. Such systems help managers solve problems by providing recommendations based on accumulated organisational or expert knowledge.

4. Document Driven Decision Support System

A Document Driven Decision Support System helps managers access, organise, search, and analyse large collections of documents. These may include reports, policies, contracts, research papers, emails, manuals, and business records. The system allows users to quickly locate relevant information when making decisions. Unlike data driven DSS, its primary focus is on textual and document based information rather than numerical data. For example, a manager considering a new project may use the system to review previous project reports, regulations, and research documents. Document driven DSS is particularly useful in organisations where important decision related information is stored in documents.

5. Communication Driven Decision Support System

A Communication Driven Decision Support System supports decision making by enabling communication, collaboration, and information sharing among two or more users. It uses technologies such as groupware, video conferencing, online meeting systems, discussion platforms, and collaborative workspaces. Team members can share information, discuss problems, generate ideas, and evaluate alternatives even when they are located in different places. For example, managers from different departments can use a communication driven DSS to discuss a new product launch and reach a common decision. It is particularly useful for group decision making, teamwork, coordination, and collaborative problem solving within organisations.

6. Hybrid Decision Support System

A Hybrid Decision Support System combines two or more DSS approaches to provide broader decision making support. It may integrate data, analytical models, expert knowledge, documents, and communication tools within a single system. For example, a business may combine customer data, forecasting models, expert recommendations, and collaboration tools to support a marketing decision. Hybrid DSS is useful when a decision requires information from multiple sources and different types of analysis. It provides greater flexibility than a single type of DSS and can support complex managerial problems. Such systems are increasingly used in modern org

Limitations of Decision Support System:

1. High Cost

Implementing a Decision Support System (DSS) can be expensive for an organisation. Costs may include software, hardware, database development, system integration, maintenance, security, and employee training. Small organisations may find it difficult to invest in sophisticated DSS technology. Additional expenses may arise when the system requires regular upgrades or specialised technical support. The cost also depends on the complexity and scale of the system. Although DSS can provide valuable decision support, organisations need to consider whether the expected benefits justify the investment. Therefore, high implementation and maintenance costs can be a significant limitation of DSS.

2. Dependence on Data Quality

The effectiveness of a DSS depends heavily on the quality, accuracy, and completeness of the data provided to it. If the input data is outdated, incomplete, incorrect, or biased, the system may produce unreliable results. A DSS cannot automatically guarantee that all information entered into the system is correct. For example, incorrect sales data may lead to inaccurate forecasts and inappropriate business decisions. Organisations therefore need proper data collection, validation, updating, and management procedures. The principle of “garbage in, garbage out” applies to DSS because poor quality input can result in poor quality analytical outputs.

3. Dependence on Human Judgement

A DSS provides information, analysis, and possible alternatives, but it generally does not replace managerial judgement. Managers must interpret the results and consider factors that may not be included in the system. These may include organisational culture, employee behaviour, ethical considerations, experience, and unexpected market conditions. Excessive dependence on system generated recommendations may cause managers to overlook important qualitative factors. Therefore, DSS should be treated as a decision support tool rather than a complete substitute for human decision making. Effective use requires managers to combine system analysis with their knowledge, experience, and professional judgement.

4. Complexity of the System

Some Decision Support Systems can be complex to design, operate, and maintain. They may involve multiple databases, analytical models, software applications, and technical components. Employees may require specialised training to understand how to use the system and interpret its results correctly. Complex systems can also be difficult to modify when business requirements change. If users do not understand the system properly, they may enter incorrect assumptions or misinterpret analytical results. Therefore, excessive complexity can reduce the practical usefulness of DSS. Organisations need user friendly interfaces, proper training, and technical support to overcome this limitation.

5. Security and Privacy Risks

DSS may process and store sensitive organisational information such as financial data, customer information, employee records, and strategic business information. If appropriate security measures are not implemented, this information may be exposed to unauthorised access, misuse, theft, or cyber attacks. Connecting DSS with multiple internal and external data sources can increase security risks. Organisations must therefore use suitable access controls, authentication, encryption, backups, and monitoring mechanisms. Data privacy requirements may also apply depending on the type of information processed. Thus, security and privacy concerns can limit the safe and effective use of Decision Support Systems.

6. Possibility of Wrong Interpretation

A DSS may produce accurate calculations but still lead to an inappropriate decision if managers misinterpret the results. Analytical outputs often depend on assumptions, models, and selected variables. If a manager does not understand these limitations, the results may be treated as more certain than they actually are. For example, a forecast may change significantly when market conditions or assumptions change. Graphs, reports, and numerical results can also be misunderstood. Therefore, managers need adequate analytical knowledge to interpret DSS outputs correctly. System generated information should be carefully evaluated before it is used for important organisational decisions.

Sampling Techniques / Methods (Probability and Non-Probability Sampling Techniques) and Sampling Tools

Sampling Techniques refer to the methods used to select individuals, items, or data points from a larger population for research purposes. These techniques ensure that the sample accurately represents the entire population, allowing for valid and reliable conclusions. Sampling techniques are broadly classified into two categories: probability sampling (where every element has an equal chance of being selected) and non-probability sampling (where selection is based on researcher judgment or convenience). Common methods include random sampling, stratified sampling, cluster sampling, convenience sampling, and purposive sampling. Choosing the right sampling technique is crucial because it impacts the quality, accuracy, and generalizability of the research findings. Proper sampling reduces bias and increases research credibility.

1. Probability Sampling Techniques

Probability sampling techniques are methods where every member of the population has a known and equal chance of being selected for the sample. These techniques aim to eliminate selection bias and ensure that the sample is truly representative of the entire population. Common types of probability sampling include simple random sampling, systematic sampling, stratified sampling, and cluster sampling. Researchers often prefer probability sampling because it allows the use of statistical methods to estimate population parameters and test hypotheses accurately. This approach enhances the validity, reliability, and generalizability of research findings, making it fundamental in scientific studies and decision-making processes.

Types of Probability Sampling Techniques

  • Simple Random Sampling

Every population member has an equal, independent chance of selection, typically using random number generators or lotteries. This method eliminates selection bias and ensures representativeness, making it ideal for homogeneous populations. However, it requires a complete sampling frame and may miss small subgroups. Despite its simplicity, large sample sizes are often needed for precision. It’s widely used in surveys and experimental research where unbiased representation is critical.

  • Stratified Random Sampling

The population is divided into homogeneous subgroups (strata), and random samples are drawn from each. This ensures representation of key characteristics (e.g., age, gender). It improves precision compared to simple random sampling, especially for heterogeneous populations. Proportionate stratification maintains population ratios, while disproportionate stratification may oversample rare groups. This method is costlier but valuable when subgroup comparisons are needed, such as in clinical or sociological studies.

  • Systematic Sampling

A fixed interval (*k*) is used to select samples from an ordered population list (e.g., every 10th person). The starting point is randomly chosen. This method is simpler than random sampling and ensures even coverage. However, if the list has hidden patterns, bias may occur. It’s efficient for large populations, like quality control in manufacturing or voter surveys, but requires caution to avoid periodicity-related distortions.

  • Cluster Sampling

The population is divided into clusters (e.g., schools, neighborhoods), and entire clusters are randomly selected for study. This reduces logistical costs, especially for geographically dispersed groups. However, clusters may lack internal diversity, increasing sampling error. Two-stage cluster sampling (randomly selecting subjects within chosen clusters) improves accuracy. It’s practical for national health surveys or educational research where individual access is challenging.

  • Multistage Sampling

A hybrid approach combining multiple probability methods (e.g., clustering followed by stratification). Large clusters are selected first, then subdivided for further random sampling. This balances cost and precision, making it useful for large-scale studies like census data collection or market research. While flexible, it requires careful design to minimize cumulative errors and maintain representativeness across stages.

2. Non-Probability Sampling Techniques

Non-probability Sampling refers to research methods where samples are selected through subjective criteria rather than random selection, meaning not all population members have an equal chance of participation. These techniques are used when probability sampling is impractical due to time, cost, or population constraints. Common approaches include convenience sampling (easily accessible subjects), purposive sampling (targeted selection of specific characteristics), snowball sampling (participant referrals), and quota sampling (pre-set subgroup representation). While these methods enable faster, cheaper data collection in exploratory or qualitative studies, they carry higher risk of bias and limit result generalizability to broader populations. Researchers employ them when prioritizing practicality over statistical representativeness.

Types of Non-Probability Sampling Techniques

  • Convenience Sampling

Researchers select participants who are most easily accessible, such as students in a classroom or shoppers at a mall. This method is quick, inexpensive, and requires minimal planning, making it ideal for preliminary research. However, results suffer from significant bias since the sample may not represent the target population. Despite limitations, convenience sampling is widely used in pilot studies, exploratory research, and when time/resources are constrained.

  • Purposive (Judgmental) Sampling

Researchers deliberately select specific individuals who meet predefined criteria relevant to the study. This technique is valuable when studying unique populations or specialized topics requiring expert knowledge. While it allows for targeted data collection, the subjective selection process introduces researcher bias. Purposive sampling is commonly used in qualitative research, case studies, and when investigating rare phenomena where random sampling isn’t feasible.

  • Snowball Sampling

Existing study participants recruit future subjects from their acquaintances, creating a chain referral process. This method is particularly useful for reaching hidden or hard-to-access populations like marginalized communities. While effective for sensitive topics, the sample may become homogeneous as participants share similar networks. Snowball sampling is frequently employed in sociological research, studies of illegal behaviors, and when investigating stigmatized conditions.

  • Quota Sampling

Researchers divide the population into subgroups and non-randomly select participants until predetermined quotas are filled. This ensures representation across key characteristics but lacks the randomness of stratified sampling. Quota sampling is more structured than convenience sampling yet still prone to selection bias. Market researchers often use this method when they need quick, cost-effective results that approximate population demographics.

  • Self-Selection Sampling

Individuals voluntarily choose to participate, typically by responding to open invitations or surveys. This approach yields large sample sizes easily but suffers from volunteer bias, as participants may differ significantly from non-respondents. Common in online surveys and call-in opinion polls, self-selection provides accessible data though results should be interpreted cautiously due to inherent representation issues.

Key differences between Probability and Non-Probability Sampling

Aspect Probability Sampling Non-Probability Sampling
Selection Basis Random Subjective
Bias Risk Low High
Representativeness High Low
Generalizability Strong Limited
Cost High Low
Time Required Long Short
Complexity High Low
Population Knowledge Required Optional
Error Control Measurable Unmeasurable
Use Cases Quantitative Qualitative
Statistical Tests Applicable Limited
Sample Frame Essential Flexible
Precision High Variable
Research Stage Confirmatory Exploratory
Participant Access Challenging Easy

Sampling Tools

Sampling tools are the techniques, procedures, or instruments used by researchers to select a suitable sample from a larger population. They help researchers identify participants systematically and ensure that the selected sample is appropriate for the research objectives. Common sampling tools and techniques include random number tables, computer-generated random selection, sampling frames, questionnaires for participant screening, and selection criteria. These tools help reduce selection bias and improve the reliability and usefulness of research findings.

Tools of Sampling

1. Sampling Frame

A sampling frame is a complete or organized list of members of the population from which the researcher selects a sample. It may contain names, identification numbers, addresses, or other relevant information. A proper sampling frame helps researchers identify eligible participants and apply sampling techniques systematically. It is particularly important in probability sampling because every suitable member should have an appropriate opportunity for selection. An accurate sampling frame reduces selection errors.

2. Random Number Table

A random number table is a traditional tool used to select participants randomly from a population. Each member is assigned a unique number, and numbers are selected from a table according to a predetermined procedure. Since selection is based on chance, personal judgment is minimized. Random number tables are useful for simple random sampling and help researchers reduce selection bias while ensuring that eligible population members have an opportunity to be included.

3. Computer Random Selection

Computer random selection uses software or digital applications to choose participants from a population. Researchers enter the sampling frame and specify the required sample size, after which the system generates random selections. This tool is faster and more convenient than manual random selection, particularly for large populations. Computer-based selection can improve accuracy and reduce human error. It is commonly used in quantitative research involving probability sampling techniques.

4. Lottery Method

The lottery method is a simple technique for selecting a random sample. Each member of the population is assigned a number or written on an identical slip, and the required number of slips is selected randomly. Every member has an equal chance of being chosen. This method is easy to understand and inexpensive to use, especially for small populations. However, it becomes difficult to manage when the population size is very large.

5. Sampling Interval

Sampling interval is a tool used mainly in systematic sampling to determine the regular gap between selected population members. It is usually calculated by dividing the population size by the desired sample size. After selecting a suitable starting point, every specified interval is chosen from the sampling frame. This approach provides an organized method of selection and can be easier to implement than simple random sampling when a complete population list is available.

6. Selection Criteria

Selection criteria are specific conditions used to determine who can participate in a research study. Researchers may establish inclusion and exclusion requirements based on the research objectives, population characteristics, or study design. Clear criteria ensure that only relevant participants are selected. They also improve consistency in sampling and reduce inappropriate selections. Well-defined criteria help researchers obtain information from participants who are directly related to the research problem.

7. Screening Questionnaire

A screening questionnaire can be used to identify participants who meet the requirements of a research study. It contains preliminary questions related to characteristics, experiences, eligibility, or other research requirements. Researchers review responses and select participants who satisfy the predetermined conditions. Screening questionnaires are particularly useful when the target population has specific characteristics. They help improve the relevance of the sample and prevent unsuitable participants from being included.

8. Sample Size Calculator

A sample size calculator is a statistical tool used to determine the appropriate number of participants required for a study. It may consider factors such as population size, confidence level, margin of error, and expected variability. Selecting an appropriate sample size helps balance accuracy and available resources. A sample that is too small may produce unreliable findings, while an unnecessarily large sample can increase time, cost, and effort.

Calculation of Interest

Calculating interest rate is not at all a difficult method to understand. Knowing to calculate interest rate can solve a lot of wages problems and save money while taking investment decisions. There is an easy formula to calculate simple interest rates. If you are aware of your loan and interest amount you can pay, you can do the largest interest rate calculation for yourself.

Using the simple interest calculation formula, you can also see your interest payments in a year and calculate your annual percentage rate.

Here is the step by step guide to calculate the interest rate.

How to calculate interest rate?

Know the formula which can help you to calculate your interest rate.

Step 1

To calculate your interest rate, you need to know the interest formula I/Pt = r to get your rate. Here,

I = Interest amount paid in a specific time period (month, year etc.)

P = Principle amount (the money before interest)

t = Time period involved

r = Interest rate in decimal

You should remember this equation to calculate your basic interest rate.

Step 2

Once you put all the values required to calculate your interest rate, you will get your interest rate in decimal. Now, you need to convert the interest rate you got by multiplying it by 100. For example, a decimal like .11 will not help much while figuring out your interest rate. So, if you want to find your interest rate for .11, you have to multiply .11 with 100 (.11 x 100).

For this case, your interest rate will be (.11 x 100 = 11) 11%.

Step 3

Apart from this, you can also calculate your time period involved, principal amount and interest amount paid in a specific time period if you have other inputs available with you.

Calculate interest amount paid in a specific time period, I = Prt.

Calculate the principal amount, P = I/rt.

Calculate time period involved t = I/Pr.

Step 4

Most importantly, you have to make sure that your time period and interest rate are following the same parameter.

For example, on a loan, you want to find your monthly interest rate after one year. In this case, if you put t = 1, you will get the final interest rate as the interest rate per year. Whereas, if you want the monthly interest rate, you have to put the correct amount of time elapsed. Here, you can consider the time period like 12 months.

Please remember, your time period should be the same time amount as the interest paid. For example, if you’re calculating a year’s monthly interest payments then, it can be considered you’ve made 12 payments.

Also, you have to make sure that you check the time period (weekly, monthly, yearly etc.) when your interest is calculated with your bank.

Step 5

You can rely on online calculators to get interest rates for complex loans, such as mortgages. You should also know the interest rate of your loan when you sign up for it.

For fluctuating rates, sometimes it becomes difficult to determine what a certain rate means. So, it is better to use free online calculators by searching “variable APR interest calculator”, “mortgage interest calculator” etc.

Calculation of interest when rate of interest and cash price is given

  • Where Cash Price, Interest Rate and Instalment are Given:

Illustration:

On 1st January 2003, A bought a television from a seller under Hire Purchase System, the cash price of which being Rs 10.450 as per the following terms:

(a) Rs 3,000 to be paid on signing the agreement.

(b) Balance to be paid in three equal installments of Rs 3,000 at the end of each year,

(c) The rate of interest charged by the seller is 10% per annum.

You are required to calculate the interest paid by the buyer to the seller each year.

Solution:

Note:

  1. there is no time gap between the signing of the agreement and the cash down payment of Rs 3,000 (1.1.2003). Hence no interest is calculated. The entire amount goes to reduce the cash price.
  2. The interest in the last installment is taken at the differential figure of Rs 285.50 (3,000 – 2,714.50).

(2) Where Cash Price and Installments are Given but Rate of Interest is Omitted:

Where the rate of interest is not given and only the cash price and the total payments under hire purchase installments are given, then the total interest paid is the difference between the cash price of the asset and the total amount paid as per the agreement. This interest amount is apportioned in the ratio of amount outstanding at the end of each period.

Illustration:

Mr. A bought a machine under hire purchase agreement, the cash price of the machine being Rs 18,000. As per the terms, the buyer has to pay Rs 4,000 on signing the agreement and the balance in four installments of Rs 4,000 each, payable at the end of each year. Calculate the interest chargeable at the end of each year.

(3) Where installments and Rate of Interest are Given but Cash Value of the Asset is Omitted:

In certain problems, the cash price is not given. It is necessary that we must first find out the cash price and interest included in the installments. The asset account is to be debited with the actual price of the asset. Under such situations, i.e. in the absence of cash price, the interest is calculated from the last year.

It may be noted that the amount of interest goes on increasing from 3rd year to 2nd year, 2nd year to 1st year. Since the interest is included in the installments and by knowing the rate of interest, we can find out the cash price.

Thus:

Let the cash price outstanding be: Rs 100

Interest @ 10% on Rs 100 for a year: Rs 10

Installment paid at the end of the year 110

The interest on installment price = 10/110 or 1/11 as a ratio.

Illustration:

I buy a television on Hire Purchase System.

The terms of payment are as follows:

Rs 2,000 to be paid on signing the agreement;

Rs 2,800 at the end of the first year;

Rs 2,600 at the end of the second year;

Rs 2,400 at the end of the third year;

Rs 2,200 at the end of the fourth year.

If interest is charged at the rate of 10% p.a., what was the cash value of the television?

Solution:

(4) Calculation of Cash Price when Reference to Annuity Table, the Rate of Interest and Installments are Given:

Sometimes in the problem a reference to annuity table wherein present value of the annuity for a number of years at a certain rate of interest is given. In such cases the cash price is calculated by multiplying the amount of installment and adding the product to the initial payment.

Illustration:

A agrees to purchase a machine from a seller under Hire Purchase System by annual installment of Rs 10,000 over a period of 5 years. The seller charges interest at 4% p.a. on yearly balance.

N.B. The present value of Re 1 p.a. for five years at 4% is Rs 4.4518. Find out the cash price of the machine.

Solution:

Installment Re 1 Present value = Rs 4.4518

Installment = Rs 10,000 Present value = Rs 4.4518 x 10,000 = Rs 44,518

Determinants of the Value of Bonds

Bonds are fixed-income securities that represent a loan from an investor to a borrower, typically a corporation or government. When purchasing a bond, the investor lends money in exchange for periodic interest payments and the return of the bond’s face value at maturity. Bonds are used to finance various projects and operations, providing a predictable income stream for investors.

Valuation of Bonds

The method for valuation of bonds involves three steps as follows:

Step 1: Estimate the expected cash flows

Step 2: Determine the appropriate interest rate that should be used to discount the cash flows.

& Step 3: Calculate the present value of the expected cash flows (step-1) using appropriate interest rate (step- 2) i.e. discounting the expected cash flows

Step 1: Estimating cash flows

Cash flow is the cash that is estimated to be received in future from investment in a bond. There are only two types of cash flows that can be received from investment in bonds i.e. coupon payments and principal payment at maturity.

The usual cash flow cycle of the bond is coupon payments are received at regular intervals as per the bond agreement, and final coupon plus principle payment is received at the maturity. There are some instances when bonds don’t follow these regular patterns. Unusual patterns maybe a result of the different type of bond such as zero-coupon bonds, in which there are no coupon payments. Considering such factors, it is important for an analyst to estimate accurate cash flow for the purpose of bond valuation.

Step 2: Determine the appropriate interest rate to discount the cash flows

Once the cash flow for the bond is estimated, the next step is to determine the appropriate interest rate to discount cash flows. The minimum interest rate that an investor should require is the interest available in the marketplace for default-free cash flow. Default-free cash flows are cash flows from debt security which are completely safe and has zero chances default. Such securities are usually issued by the central bank of a country, for example, in the USA it is bonds by U.S. Treasury Security.

Consider a situation where an investor wants to invest in bonds. If he is considering to invest corporate bonds, he is expecting to earn higher return from these corporate bonds compared to rate of returns of U.S. Treasury Security bonds. This is because chances are that a corporate bond might default, whereas the U.S. Security Treasury bond is never going to default. As he is taking a higher risk by investing in corporate bonds, he expects a higher return.

One may use single interest rate or multiple interest rates for valuation.

Step 3: Discounting the expected cash flows

Now that we already have values of expected future cash flows and interest rate used to discount the cash flow, it is time to find the present value of cash flows. Present Value of a cash flow is the amount of money that must be invested today to generate a specific future value. The present value of a cash flow is more commonly known as discounted value.

The present value of a cash flow depends on two determinants:

  • When a cash flow will be received i.e. timing of a cash flow &;
  • The required interest rate, more widely known as Discount Rate (rate as per Step-2)

First, we calculate the present value of each expected cash flow. Then we add all the individual present values and the resultant sum is the value of the bond.

The formula to find the present value of one cash flow is:

Present value formula for Bond Valuation

Present Value n = Expected cash flow in the period n/ (1+i) n

Here,

i = rate of return/discount rate on bond
n = expected time to receive the cash flow

By this formula, we will get the present value of each individual cash flow t years from now. The next step is to add all individual cash flows.

Bond Value = Present Value 1 + Present Value 2 + ……. + Present Value n

Research, Introduction, Meaning, Definition, Objective, Purpose, Types, Importance and Challenges

Research is a systematic and organized process of collecting, analyzing, and interpreting information to increase understanding of a topic or issue. It aims to discover new facts, verify existing knowledge, or solve specific problems through careful investigation. Research can be theoretical or applied, and it involves forming hypotheses, gathering data, and drawing conclusions. It is essential in academic, scientific, and business fields to make informed decisions and improve practices. A well-conducted research study follows a structured methodology to ensure reliability and validity. Overall, research is a tool for expanding knowledge and contributing to the development of society and industries.

Definition of Research

  • Clifford Woody

Research is a careful inquiry or examination to discover new facts or verify old ones.

  • Creswell

Research is a process of steps used to collect and analyze information to increase our understanding of a topic.

  • Redman and Mory

Research is a systematized effort to gain new knowledge.

  • Kerlinger

Research is a systematic, controlled, empirical, and critical investigation of hypothetical propositions.

  • Lundberg

Research is a systematic activity directed towards the discovery and development of an organized body of knowledge.

Objective of Research

  • To Gain Familiarity with a Phenomenon

One major objective of research is to explore and understand a phenomenon or concept more clearly. This is often done through exploratory research, especially when little prior knowledge exists. It helps researchers gain insights into new topics, identify trends, and lay the groundwork for future studies. By becoming familiar with unfamiliar issues, researchers can form better hypotheses and research questions. This foundational understanding is critical for developing more in-depth research and creating meaningful contributions to academic and professional fields.

  • To Describe a Phenomenon Accurately

Descriptive research aims to systematically and precisely describe the characteristics of a subject, event, or population. Whether it’s human behavior, market trends, or institutional processes, this type of research collects detailed information to create an accurate picture. The objective is not to determine cause-and-effect but to define “what is” in a clear and factual manner. Such descriptions help researchers, practitioners, and policymakers understand the current state of affairs and serve as a reference point for comparing future changes.

  • To Establish Cause-and-Effect Relationships

Causal or explanatory research seeks to identify and analyze relationships between variables, often using experiments or observational studies. The objective is to determine how and why certain phenomena occur. For instance, a business might study the impact of advertising on sales. Establishing cause-and-effect allows researchers to predict outcomes and design effective interventions. This type of research is essential in fields like science, economics, and medicine, where understanding the effects of one factor on another can lead to critical discoveries and solutions.

  • To Test Hypotheses

Another key objective of research is hypothesis testing, where assumptions or predictions made before a study are examined for accuracy. Researchers design experiments or surveys to gather data that supports or refutes their hypotheses. The goal is to provide empirical evidence for or against theoretical statements. This process sharpens theories, confirms findings, and promotes scientific accuracy. Testing hypotheses is particularly important in quantitative research, as it relies on statistical techniques to validate conclusions and ensure objectivity.

  • To Develop New Theories and Concepts

Research often leads to the creation or refinement of theories and models that explain how the world works. The objective here is to go beyond existing knowledge and offer new perspectives or conceptual frameworks. Through in-depth analysis, researchers can challenge outdated views and propose innovative explanations. These new theories guide future research, inform policy, and influence practice across disciplines. In academic fields, theoretical research forms the basis for scholarly progress and intellectual advancement.

  • To Find Solutions to Practical Problems

Applied research is conducted with the specific objective of solving real-world problems. Whether it’s improving product design, enhancing public health, or increasing workplace efficiency, the goal is to apply scientific methods to practical challenges. This kind of research is widely used in industries, education, and government. It not only addresses current issues but also anticipates future needs. By developing effective strategies and solutions, applied research makes a direct contribution to societal well-being and economic development.

  • To Predict Future Trends

Research aims to forecast what may happen in the future based on current and past data. Predictive research uses statistical tools and modeling techniques to identify patterns and trends that inform future outcomes. For example, businesses use market research to predict consumer behavior, and climate scientists use data to forecast environmental changes. These predictions guide planning and strategic decisions. Accurate forecasting is essential for minimizing risk, improving preparedness, and making proactive decisions in dynamic environments.

  • To Enhance Understanding and Clarify Doubts

Research helps deepen our understanding of complex topics and clarifies uncertainties that may exist in previous studies or beliefs. By investigating issues from multiple angles, using various methods, and verifying results, research ensures greater clarity and accuracy. This objective is crucial in academia and science, where incomplete or conflicting information often leads to confusion. Ongoing research contributes to refinement, resolution of debates, and filling knowledge gaps, ensuring a more complete and reliable understanding of any subject.

Purpose of Research

  • Discovery of New Knowledge

One of the primary purposes of research is to discover new facts, ideas, and knowledge. Research helps in expanding the existing pool of information by exploring unknown areas and generating fresh insights. Through systematic investigation, researchers identify new relationships, concepts, and principles that were previously unexplored. This contributes to the growth of various disciplines such as science, management, economics, and social sciences. Discovery-oriented research lays the foundation for innovation, development, and further academic inquiry in different fields of study.

  • Verification of Existing Knowledge

Research is conducted to test and verify the validity of existing theories, laws, and concepts. Many ideas accepted over time require re-examination due to changing conditions, new evidence, or technological advancements. Research helps confirm whether earlier findings are still relevant and accurate. This process strengthens the reliability of knowledge by removing errors, misconceptions, and outdated assumptions. Verification through research ensures that decisions, policies, and practices are based on dependable and scientifically tested information.

  • Solution to Practical Problems

Another important purpose of research is to provide solutions to real-life problems faced by individuals, organizations, industries, and society. Applied research focuses on identifying causes of problems and suggesting effective remedies. In business, research helps solve issues related to production, marketing, finance, and human resources. In social sciences, it addresses problems like poverty, unemployment, and health. Thus, research acts as a tool for problem-solving and practical decision-making.

  • Development of Theories and Concepts

Research helps in developing new theories, models, and conceptual frameworks. By analyzing data and observing patterns, researchers formulate generalizations and principles that explain phenomena. These theories provide a systematic understanding of relationships among variables and guide future research. Theory-building research enhances academic depth and strengthens subject foundations. It also helps practitioners apply theoretical knowledge in practical situations, thereby bridging the gap between theory and practice in various disciplines.

  • Prediction and Forecasting

Research plays a significant role in predicting future trends and outcomes. By studying past and present data, researchers can forecast changes in markets, consumer behavior, population growth, and economic conditions. Such predictions help organizations and governments plan for the future and reduce uncertainty. Forecasting through research supports strategic planning, risk management, and policy formulation. Accurate predictions enable better preparedness for challenges and opportunities that may arise in the future.

  • Improvement in Decision Making

One of the key purposes of research is to support sound and rational decision-making. Research provides relevant, accurate, and timely information required for making informed choices. In business and management, research reduces guesswork and reliance on intuition. Decisions related to investment, product development, and policy implementation become more effective when backed by research findings. Thus, research improves the quality of decisions and enhances efficiency and effectiveness in achieving objectives.

  • Advancement of Social and Economic Development

Research contributes significantly to social and economic progress. It helps identify social issues, evaluate government programs, and suggest improvements in public policies. Economic research aids in understanding growth patterns, inflation, employment, and income distribution. Through research, innovative solutions are developed to improve living standards and promote sustainable development. Hence, research supports national development by providing a scientific basis for planning, reforms, and welfare initiatives.

  • Enhancement of Knowledge and Learning

Research promotes intellectual growth and continuous learning. It develops analytical thinking, creativity, and problem-solving abilities among researchers and students. Through research, individuals gain deeper understanding of subjects and develop a scientific attitude. It encourages questioning, exploration, and logical reasoning. This purpose is especially important in education, where research-based learning improves academic quality and contributes to personal and professional development.

Types of Research

1. Basic Research

Basic research, also known as pure or fundamental research, is conducted to expand existing knowledge without focusing on immediate practical application. Its main objective is to develop theories, principles, and generalizations. This type of research helps in understanding fundamental aspects of a subject and provides a foundation for applied research. Although it may not offer direct solutions, basic research is essential for long-term academic growth and scientific advancement.

2. Applied Research

Applied research is undertaken to solve specific, practical problems faced by individuals, organizations, or society. It focuses on applying theoretical knowledge to real-life situations. This type of research is common in fields like business, management, medicine, and engineering. The findings of applied research are directly useful for decision-making and problem-solving. It helps improve products, processes, and services by providing workable solutions.

3. Descriptive Research

Descriptive research aims to describe the characteristics of a population, situation, or phenomenon accurately. It does not control variables but observes and reports conditions as they exist. Surveys, questionnaires, and observational methods are commonly used. This type of research helps in understanding “what is happening” rather than “why it happens.” Descriptive research is widely used in social sciences, marketing, and business studies.

4. Analytical Research

Analytical research involves the use of existing data to analyze and evaluate relationships among variables. The researcher critically examines facts and information to draw conclusions. Unlike descriptive research, analytical research focuses on “why” and “how” aspects. It requires logical reasoning and statistical tools. This type of research is useful in policy analysis, financial studies, and economic research to understand cause-and-effect relationships.

5. Exploratory Research

Exploratory research is conducted when a problem is not clearly defined or when little information is available. Its purpose is to gain initial insights and understanding of the problem. Methods such as interviews, focus groups, and literature reviews are commonly used. Exploratory research helps in formulating hypotheses and identifying variables for further study. It provides direction for more detailed and structured research.

6. Qualitative Research

Qualitative research focuses on understanding human behavior, opinions, and experiences in a non-numerical form. It uses methods like interviews, case studies, and observations. This type of research emphasizes depth rather than quantity of data. Qualitative research helps in exploring attitudes, motivations, and perceptions. It is widely used in social sciences, psychology, and management to gain detailed insights.

7. Quantitative Research

Quantitative research deals with numerical data and statistical analysis. It aims to quantify variables and examine relationships using structured tools like surveys and experiments. This type of research provides measurable and objective results. Quantitative research is useful for testing hypotheses and making generalizations. It is commonly used in business, economics, and scientific studies where precision and accuracy are required.

8. Conceptual and Empirical Research

Conceptual research is based on abstract ideas, theories, and concepts. It involves logical reasoning and theoretical analysis without relying on observation. Empirical research, on the other hand, is based on actual observations and experiments. It relies on data collection and evidence. Both types are important, as conceptual research builds theories, while empirical research tests and validates them in real-world conditions.

Importance of Research

  • Expansion of Knowledge

Research plays a vital role in expanding human knowledge. It helps us understand concepts, theories, and facts in a deeper and more meaningful way. Through systematic investigation, research uncovers hidden truths and broadens the scope of what is already known. This continuous process of discovery is essential in education, science, and innovation. Without research, the development of new ideas, improvements in technology, and advancements in various fields would come to a standstill.

  • Problem Solving

One of the main purposes of research is to find solutions to problems. In both academic and practical settings, research helps identify the root causes of issues and suggests possible remedies. Whether it’s a social, economic, scientific, or business problem, research provides the tools and frameworks to analyze the situation effectively. It allows decision-makers to make evidence-based choices and implement strategies that are backed by data and analysis, leading to more successful outcomes.

  • Informed Decision Making

Research enables individuals, organizations, and governments to make informed decisions. By analyzing data and studying trends, research provides a factual basis for choosing between alternatives. In business, it helps managers decide on product development, marketing strategies, and investment plans. In public policy, it helps lawmakers craft laws that address real needs. This reduces the risk of failure and ensures that decisions are effective, efficient, and aligned with actual conditions and demands.

  • Economic Development

Research is essential for economic growth and development. It leads to the creation of new products, services, and technologies, which drive industry and generate employment. By improving productivity, reducing costs, and increasing competitiveness, research directly contributes to the success of businesses and national economies. Additionally, research in areas like agriculture, health, and education ensures sustainable development by solving real-world problems and improving the quality of life for individuals and communities.

  • Improvement in Education

Research strengthens the education system by improving teaching methods, learning outcomes, and academic content. It helps educators understand student needs, evaluate curricula, and adopt innovative practices. Research also enables students and teachers to stay updated with the latest knowledge in their field, promoting lifelong learning. Educational research contributes to the development of better textbooks, e-learning tools, and inclusive teaching strategies that cater to diverse learning styles and backgrounds.

  • Policy Formulation

Government and institutional policies must be based on reliable data and analysis, which research provides. Whether in health, education, environment, or public safety, research ensures that policies are relevant, effective, and future-ready. It helps policymakers assess the potential impact of laws and regulations, avoiding guesswork and promoting social welfare. Evidence-based policies are more likely to gain public support and achieve their goals, ultimately benefiting the economy and society as a whole.

  • Innovation and Technology Advancement

Innovation thrives on research. From developing new medical treatments to designing smarter devices, research is the foundation of technological progress. Scientists and engineers rely on research to explore possibilities, test ideas, and turn concepts into real-world applications. Research also encourages creativity and collaboration across disciplines, pushing the boundaries of what’s possible. As technology rapidly evolves, research ensures that innovation continues to meet the needs of people and adapt to changing environments.

  • Social and Cultural Understanding

Research deepens our understanding of social and cultural dynamics. It helps explore human behavior, beliefs, traditions, and societal changes. Through research in fields like sociology, anthropology, and psychology, we gain insights into communities and cultures, fostering tolerance and mutual respect. This understanding is crucial in a globalized world where collaboration and coexistence are key. It also helps in addressing social issues like poverty, gender inequality, and discrimination with informed, data-backed strategies.

Challenges in Research

  • Problem Identification and Definition

One of the major challenges in research is identifying and clearly defining the research problem. An unclear or poorly framed problem leads to confusion and ineffective results. Researchers often face difficulty in narrowing down a broad topic into a specific and researchable problem. Lack of clarity affects objectives, hypothesis formulation, and methodology. Proper understanding of the problem is essential, as the entire research process depends on accurate problem identification and precise definition.

  • Availability of Reliable Data

Availability of accurate and reliable data is a significant challenge in research. Researchers may face incomplete, outdated, or inconsistent data sources. In some cases, data may not be accessible due to confidentiality or restrictions. Primary data collection can be costly and time-consuming, while secondary data may lack relevance. Poor quality data directly affects the validity and reliability of research findings, making conclusions less dependable.

  • Time Constraints

Time limitation is a common challenge faced by researchers, especially students and professionals. Research involves multiple stages such as literature review, data collection, analysis, and reporting, each requiring adequate time. Due to academic deadlines or organizational pressure, researchers may rush through processes, leading to errors and superficial analysis. Insufficient time affects depth, accuracy, and overall quality of research work.

  • Financial Constraints

Lack of adequate funds poses a major challenge in conducting research. Expenses related to data collection, fieldwork, surveys, software, and expert consultation can be high. Limited financial resources restrict sample size, research tools, and scope of the study. Due to budget constraints, researchers may compromise on quality and methodology, which negatively impacts the reliability and effectiveness of research outcomes.

  • Selection of Appropriate Research Methodology

Choosing the correct research methodology is often challenging. Researchers may struggle to select suitable research design, sampling techniques, and data collection methods. Incorrect methodology leads to biased results and invalid conclusions. Lack of experience or guidance further complicates this challenge. Proper alignment between research objectives and methodology is crucial to ensure meaningful and accurate findings.

  • Researcher Bias and Subjectivity

Researcher bias is a serious challenge that affects objectivity. Personal beliefs, assumptions, and expectations may influence data collection, interpretation, and conclusions. Bias can occur intentionally or unintentionally, leading to distorted results. Maintaining neutrality and using standardized tools is essential. Overcoming bias requires awareness, ethical conduct, and adherence to scientific principles throughout the research process.

  • Ethical Issues in Research

Ethical challenges are common in research involving human subjects. Issues such as informed consent, privacy, confidentiality, and data misuse must be carefully handled. Researchers may face difficulty in balancing research objectives with ethical responsibilities. Failure to follow ethical standards can lead to legal consequences and loss of credibility. Ethical compliance is essential for responsible and trustworthy research.

  • Data Analysis and Interpretation

Analyzing and interpreting data accurately is a complex challenge in research. Researchers may lack technical knowledge of statistical tools and software. Misinterpretation of data can lead to incorrect conclusions. Large volumes of data increase complexity and chances of error. Proper training, use of appropriate analytical techniques, and careful interpretation are necessary to ensure valid and meaningful research results.

Future Value, Functions, Types

Future Value (FV) is the value of a current asset at a future date based on an assumed rate of growth. The future value (FV) is important to investors and financial planners as they use it to estimate how much an investment made today will be worth in the future. Knowing the future value enables investors to make sound investment decisions based on their anticipated needs.

FV calculation allows investors to predict, with varying degrees of accuracy, the amount of profit that can be generated by different investments. The amount of growth generated by holding a given amount in cash will likely be different than if that same amount were invested in stocks; so, the FV equation is used to compare multiple options.

Determining the FV of an asset can become complicated, depending on the type of asset. Also, the FV calculation is based on the assumption of a stable growth rate. If money is placed in a savings account with a guaranteed interest rate, then the FV is easy to determine accurately. However, investments in the stock market or other securities with a more volatile rate of return can present greater difficulty.

Future Value (FV) formula assumes a constant rate of growth and a single upfront payment left untouched for the duration of the investment. The FV calculation can be done one of two ways depending on the type of interest being earned. If an investment earns simple interest, then the Future Value (FV) formula is:

  • Future value (FV) is the value of a current asset at some point in the future based on an assumed growth rate.
  • Investors are able to reasonably assume an investment’s profit using the future value (FV) calculation.
  • Determining the future value (FV) of a market investment can be challenging because of the market’s volatility.
  • There are two ways of calculating the future value (FV) of an asset: FV using simple interest and FV using compound interest.

Functions of Future Value:

  • Investment Growth Measurement:

FV is used to calculate how much an investment will grow over time. By applying a specified interest rate, investors can estimate the future worth of their initial investments or savings, helping them understand the potential returns.

  • Retirement Planning:

FV plays a critical role in retirement planning. Individuals can determine how much they need to save today to achieve a desired retirement income. By calculating the future value of regular contributions to retirement accounts, they can set realistic savings goals.

  • Loan Repayment Calculations:

For borrowers, FV is crucial in understanding the total amount owed on loans over time. It helps them visualize the long-term cost of borrowing, including interest payments, aiding in budgeting and financial decision-making.

  • Comparison of Investment Opportunities:

FV provides a standardized way to compare different investment options. By calculating the future value of various investment opportunities, investors can evaluate which options offer the highest potential returns over a specified period.

  • Education Funding:

Parents can use FV to plan for their children’s education expenses. By estimating future tuition costs and calculating how much they need to save now, parents can ensure they accumulate sufficient funds by the time their children enter college.

  • Inflation Adjustment:

FV helps investors account for inflation when planning for future expenses. By incorporating an expected inflation rate into future value calculations, individuals and businesses can better estimate the amount needed to maintain purchasing power over time.

Future Value of a Single Flow:

This occurs when a single sum of money is invested for a certain period at a given interest rate.

Formula:

FV = PV × (1+r)^n

Example:

Suppose ₹10,000 is invested for 3 years at 10% annual interest.

Year Calculation Future Value (₹)

3

₹10,000 × (1 + 0.10)^3

₹13,310

Kurtosis, Concepts, Definition, Types, Significance and Interpretation of Kurtosis in Statistical Analysis

Kurtosis is a statistical measure that describes the degree of peakedness or flatness of a frequency distribution in comparison with a normal distribution. It indicates how observations are concentrated around the mean and how the tails of the distribution behave.

In Business Statistics, kurtosis helps analysts understand the shape of a distribution and identify whether data contains extreme observations. It is widely used in finance, economics, market research, quality control, and risk analysis.

Definition of Kurtosis

Kurtosis is the measure of the shape of a distribution that indicates the extent to which observations cluster around the center and the thickness of the tails relative to a normal distribution.

The term Kurtosis was introduced by Karl Pearson.

Excess Kurtosis

An excess kurtosis is a metric that compares the kurtosis of a distribution against the kurtosis of a normal distribution. The kurtosis of a normal distribution equals 3. Therefore, the excess kurtosis is found using the formula below:

Excess Kurtosis = Kurtosis – 3

Significance of Kurtosis

1. Understanding the Shape of Distribution

Kurtosis is an important statistical measure that describes the shape of a frequency distribution, particularly the heaviness of its tails compared with a normal distribution. It helps identify whether a distribution has relatively heavy or light tails. By studying kurtosis, researchers can understand how observations are distributed around the centre and in the extreme regions. Therefore, kurtosis provides additional information about data characteristics that cannot be fully explained by measures of central tendency and dispersion alone.

2. Identifying Extreme Values

Kurtosis is useful for understanding the tendency of a distribution to produce extreme observations. Distributions with heavier tails may have a greater tendency to contain unusually high or low values compared with a normal distribution. This information is important when examining income, profits, losses, and examination marks. However, kurtosis does not identify specific outliers or directly measure their number. Researchers should combine kurtosis with graphical methods and other statistical measures to investigate unusual observations accurately.

3. Comparing Different Distributions

Kurtosis helps compare the distributional characteristics of two or more datasets. Even when datasets have similar means and standard deviations, they may differ in their tail behaviour. Comparing kurtosis values helps researchers identify whether one distribution has relatively heavier or lighter tails than another. This comparison is useful in economics, business, finance, and scientific research. However, kurtosis should not be interpreted as a complete description of distribution shape because different distributions can have similar kurtosis values.

4. Financial Risk Analysis

In finance, kurtosis is significant for analysing investment returns and understanding the possibility of unusually large gains or losses. Financial return distributions with heavy tails may experience extreme outcomes more frequently than a normal distribution would suggest. Investors and financial analysts can use kurtosis alongside volatility and other risk measures to evaluate potential exposure to extreme market movements. This information supports risk assessment and portfolio management, although kurtosis alone cannot predict when extreme events will occur or how severe they will be.

5. Supporting Statistical Analysis

Kurtosis helps researchers examine whether data differ from the characteristics commonly associated with a normal distribution. Some statistical methods rely on assumptions about distributional behaviour, so understanding kurtosis can assist in evaluating whether further investigation is necessary. A high or low kurtosis value may indicate that the data require closer examination before applying particular analytical techniques. Researchers can consider transformations or alternative methods when appropriate. Therefore, kurtosis supports more careful statistical planning and improves the interpretation of analytical results.

6. Analysing Business Data

Businesses use kurtosis to examine distributions of sales, profits, costs, customer spending, and transaction values. A distribution with heavy tails may indicate that unusually large or small business outcomes occur more often than expected under a normal distribution. Managers can investigate these patterns to improve budgeting, forecasting, and operational planning. For example, unusual sales values may require further examination before setting future targets. When combined with other statistical measures, kurtosis helps businesses understand variability and evaluate potential unexpected outcomes.

7. Evaluating Data Consistency

Kurtosis provides additional information about the distribution of observations and can help researchers assess whether datasets contain unusual tail behaviour. Comparing kurtosis across groups or time periods may reveal changes in the frequency of extreme outcomes. This can be useful in quality control, production analysis, and performance evaluation. However, kurtosis does not directly measure consistency or overall variability. Researchers should interpret it alongside the standard deviation, range, and graphical summaries to develop a reliable understanding of the dataset.

8. Supporting Research and Decision-Making

Kurtosis is useful in economics, education, social sciences, and scientific research because it describes an important aspect of distribution shape. Researchers can use it to compare examination results, household expenditure, population measurements, and experimental observations. Understanding tail behaviour helps them recognise when unusual values may influence conclusions. Kurtosis can also guide further investigation into the characteristics of a dataset. Therefore, it contributes to informed decision-making when used alongside suitable descriptive statistics, visualisations, and analytical methods.

Types of Kurtosis

The types of kurtosis are determined by the excess kurtosis of a particular distribution. The excess kurtosis can take positive or negative values as well, as values close to zero.

1. Mesokurtic

Mesokurtic Distribution is a distribution that has the same degree of peakedness and tail thickness as a normal distribution. It serves as the standard or benchmark against which other types of kurtosis are compared. In a mesokurtic distribution, observations are moderately concentrated around the mean, and the tails are neither too heavy nor too light. The coefficient of kurtosis (β₂) is equal to 3, while excess kurtosis is 0. Many natural and social phenomena approximately follow a mesokurtic pattern. This type of distribution indicates a balanced spread of data without an unusual concentration of extreme values. In business statistics, mesokurtic distributions are often considered ideal because they reflect a normal and predictable pattern of observations.

Example: The distribution of examination scores in a large class often approximates a mesokurtic distribution.

2. Leptokurtic

Leptokurtic Distribution is more peaked than a normal distribution and has heavier tails. In this type of distribution, a large number of observations are concentrated near the mean, while the tails contain more extreme values than a normal distribution. The coefficient of kurtosis (β₂) is greater than 3, and excess kurtosis is positive. Because of its heavy tails, a leptokurtic distribution indicates a higher probability of extreme observations occurring. This characteristic is particularly important in finance and investment analysis, where sudden gains or losses may occur. In business statistics, leptokurtic distributions are useful for identifying situations involving high risk and volatility. The presence of a sharp peak and heavy tails suggests that observations cluster around the center but occasionally produce significant deviations from the average.

Example: Stock market returns often follow a leptokurtic distribution because extreme gains and losses occur more frequently than expected under a normal distribution.

3. Platykurtic

Platykurtic Distribution is flatter than a normal distribution and has lighter tails. In this type of distribution, observations are more evenly spread across the range of data, resulting in a broad and low central peak. The coefficient of kurtosis (β₂) is less than 3, while excess kurtosis is negative. Because the tails are lighter, extreme observations occur less frequently than in a normal distribution. A platykurtic distribution indicates greater dispersion and lower concentration of observations around the mean. In business statistics, such distributions may occur when data is uniformly distributed across different categories. The flatter shape suggests that observations are widely dispersed and that the likelihood of unusually high or low values is relatively small.

Example: The distribution of customer arrivals spread evenly throughout a day may exhibit a platykurtic pattern.

Interpretation of Kurtosis in Statistical Analysis

1. Mesokurtic Distribution

A mesokurtic distribution has kurtosis similar to that of a normal distribution. Its tail behaviour is considered comparable to the normal distribution, making it a useful reference point for statistical analysis. When using excess kurtosis, a mesokurtic distribution has a value of zero. This distribution is commonly used as a benchmark when comparing the kurtosis of other datasets. However, zero excess kurtosis alone does not prove that a distribution is perfectly normal.

2. Leptokurtic Distribution

A leptokurtic distribution has positive excess kurtosis, indicating heavier tails than a normal distribution. Such distributions may have a greater tendency to produce extreme observations, including unusually high or low values. In financial analysis, this characteristic is important because investment returns may experience extreme movements more frequently than a normal model predicts. Leptokurtic distributions can also appear in business and economic data. Researchers should examine the entire distribution before drawing conclusions about its shape.

3. Platykurtic Distribution

A platykurtic distribution has negative excess kurtosis, indicating lighter tails than a normal distribution. It generally suggests a lower tendency to produce extreme observations compared with a normal distribution. Such distributions may appear relatively flatter or more spread across the central region, although kurtosis alone does not determine the complete shape. This interpretation is useful when comparing examination marks, business measurements, or other datasets. Researchers should also consider the mean, standard deviation, and graphical representation.

4. Interpretation Using Excess Kurtosis

Kurtosis is commonly interpreted using excess kurtosis, which is calculated by subtracting three from the ordinary kurtosis value. Under this convention, zero indicates kurtosis equal to that of a normal distribution, a positive value indicates heavier tails, and a negative value indicates lighter tails. For example, excess kurtosis of +2 indicates positive excess kurtosis, while −1 indicates negative excess kurtosis. This method provides a convenient basis for comparing the tail behaviour of different distributions.

5. Identifying Extreme Observations

Kurtosis helps researchers understand whether a distribution has relatively heavy or light tails compared with a normal distribution. Higher kurtosis may indicate a greater tendency for extreme observations, while lower kurtosis may indicate lighter tails. This information is useful for examining unusual incomes, business profits, examination scores, and investment returns. However, kurtosis does not identify individual outliers or establish their causes. Researchers should use histograms, box plots, and other statistical measures to investigate extreme observations more accurately.

6. Comparing Different Datasets

Kurtosis is useful for comparing the tail characteristics of two or more datasets. For example, two groups may have similar means and standard deviations but different excess kurtosis values. The group with higher excess kurtosis may exhibit heavier tails relative to a normal distribution. Such comparisons can support business analysis, economic research, and quality control. Nevertheless, similar kurtosis values do not guarantee similar distribution shapes, so researchers should consider other descriptive statistics and graphical methods when comparing datasets.

7. Application in Financial Risk Analysis

In financial analysis, kurtosis helps assess the possibility of unusually large gains or losses in investment returns. Positive excess kurtosis suggests heavier tails than a normal distribution, meaning extreme outcomes may occur more frequently than a normal model predicts. This information can support risk assessment and portfolio analysis. However, kurtosis alone cannot predict the timing or size of future market movements. Investors should also examine volatility, market conditions, and other risk measures before making financial decisions.

Methods of Primary Data Collection: Observation, Interview, Questionnaire, and Survey

Primary Data is information collected firsthand by a researcher for a specific research purpose. It is original, fresh, and tailored directly to the research question or objective. Methods such as surveys, interviews, experiments, and observations are commonly used to gather primary data. Since it is collected directly from the source, primary data is highly relevant, specific, and accurate. However, it often requires more time, effort, and resources compared to using existing information. It is essential for studies needing updated or detailed insights.

Methods of Primary Data Collection:

  • Observation

Observation involves systematically watching and recording behaviors, events, or phenomena as they occur naturally or in a controlled setting. It allows researchers to gather real-time, unbiased data without influencing the subject’s behavior. Observations can be structured (following a predefined checklist) or unstructured (open-ended). It is especially useful when participants are unwilling or unable to provide accurate verbal responses. Researchers may act as participants (participant observation) or as non-intrusive observers. Observation is widely used in fields like anthropology, psychology, and marketing to understand behaviors, workflows, or consumer interactions. It provides deep insights but may sometimes lack the ability to explain the reasons behind certain actions, requiring combination with other methods like interviews for richer analysis.

  • Interview

An interview is a direct, face-to-face, telephonic, or video-based conversation between the researcher and the participant aimed at gathering detailed information. Interviews can be structured (fixed questions), semi-structured (guided by a framework but flexible), or unstructured (open conversation). This method allows for in-depth exploration of opinions, emotions, experiences, and motivations. Interviews can be personal or group-based, depending on research needs. They are commonly used in qualitative research to gain comprehensive understanding and context behind responses. Although interviews provide rich, detailed data, they can be time-consuming and may introduce biases if not conducted carefully. Proper interviewer skills are essential for encouraging honest and open communication from participants.

  • Questionnaire

Questionnaire is a set of written or digital questions designed to collect information from respondents. It can include closed-ended questions (like multiple-choice) or open-ended questions (where respondents write answers in their own words). Questionnaires are often used for surveys and research studies where standardized information is needed from a large audience. They are cost-effective, easy to distribute, and efficient in data collection. Responses are easy to quantify for statistical analysis. However, the design of the questionnaire is crucial — poorly framed questions can lead to misunderstandings and unreliable data. Questionnaires are widely used in education, social science, market research, and customer satisfaction studies.

  • Survey

Survey is a research method involving the systematic collection of information from a sample of individuals, usually through questionnaires or interviews. Surveys can be conducted in-person, via phone, online, or by mail. They are useful for gathering quantitative as well as qualitative data about behaviors, attitudes, preferences, or demographics. Surveys are popular because they can cover large populations at relatively low cost and produce statistically significant results if designed properly. However, their effectiveness depends on clear question framing, respondent honesty, and sampling methods. Surveys are widely used in fields like business, healthcare, political science, and social research for decision-making and trend analysis.

Management Information System (MIS), Concept, Features, Components, Types, Process, Advantages and Disadvantages

Management Information System (MIS) is a computer-based system that provides managers with the tools to organize, evaluate, and efficiently manage departments within an organization. Its primary purpose is to transform raw data from Transaction Processing Systems (TPS) into structured, summarized reports to support tactical decision-making. MIS focuses on monitoring, controlling, and planning current operations by presenting historical data in routine, scheduled formats like dashboards, summary reports, and trend analyses. By delivering relevant, timely information on key performance indicators (KPIs), it empowers middle management to compare actual performance against targets, identify issues, and ensure the smooth, efficient running of the business.

Features of Management Information Systems (MIS):

1. Management-Oriented and Driven

The design and development of an MIS are top-down, initiated by the needs of management. The system is built with the explicit purpose of serving the information requirements of managers at various levels—strategic, tactical, and operational. This ensures that the system outputs (reports, dashboards) are tailored to support specific managerial functions like planning, controlling, and decision-making. It is not a byproduct of operational data but a deliberate architecture to provide actionable intelligence, making it an essential tool for directing organizational performance and achieving business objectives.

2. Integrated System from Disparate Sources

A core feature of MIS is its ability to integrate data from various functional departments and Transaction Processing Systems (TPS) across the organization. It consolidates inputs from finance, marketing, production, and human resources into a unified database. This breaks down information silos and provides a holistic, cross-functional view of the organization. Integration ensures consistency, eliminates data redundancy, and allows managers to see the interconnected impact of decisions across different units, fostering coordinated and aligned actions throughout the enterprise.

3. Timely and Scheduled Reporting

MIS is designed to provide information when it is needed, following a structured reporting schedule. It generates reports daily, weekly, monthly, or quarterly, ensuring managers receive consistent updates on performance metrics. While not always real-time like a TPS, its timeliness is aligned with managerial review cycles. For example, a weekly sales summary allows a regional manager to take corrective action promptly. This predictable, scheduled flow of information supports routine planning and control activities, enabling proactive rather than reactive management.

4. Exception-Based Reporting

Beyond standard summaries, a sophisticated MIS includes exception reporting. It is programmed to highlight significant deviations from planned performance or predefined thresholds. For instance, it can automatically flag a product line where sales have fallen 15% below target or a department that has exceeded its budget. This feature directs managerial attention to areas requiring immediate intervention, improving efficiency by allowing managers to focus on critical issues and exceptions rather than sifting through volumes of routine data.

5. Support for Structured and Semi-Structured Decisions

MIS primarily aids in making structured and semi-structured decisions at the tactical and operational levels. These are recurring decisions with known information requirements, such as inventory reordering, budget allocation, or staff scheduling. By providing summarized historical data and comparative analyses, MIS reduces uncertainty and provides a factual basis for these decisions. It supports “what-if” analysis for semi-structured scenarios, helping managers evaluate the potential outcomes of different choices within a defined framework.

6. Use of Internal and Historical Data

MIS primarily relies on internal, historical data sourced from the organization’s own TPS and databases. It processes and summarizes past transactions to identify trends, patterns, and performance over time. While some systems may incorporate limited external data (e.g., market indices), the focus is on leveraging internal records to assess efficiency, productivity, and compliance with internal plans and budgets. This inward-looking analysis is crucial for internal control and operational optimization.

7. User-Friendly Output and Presentation

Effective communication of information is key. MIS provides outputs in easily understandable formats for non-technical managers. This includes structured reports, graphical dashboards, charts, and summaries. The presentation is designed to highlight key metrics and trends at a glance, facilitating quick comprehension and decision-making. The focus is on transforming complex data sets into clear, actionable intelligence, making the system accessible and valuable to its primary users—the management team.

8. Flexibility and Future-Oriented Design

While based on historical data, a well-designed MIS is built with flexibility to adapt to changing information needs. It should allow for the generation of ad-hoc reports and be scalable to include new data sources or reporting modules as the business evolves. This future-oriented design ensures the system remains relevant, supporting not just current operational control but also aiding in the formulation of future plans and strategies based on analyzed trends.

Components of Management Information Systems (MIS):

1. Data Resources

The data resource is the foundational component of any MIS. It comprises the structured collection of internal transactional data from TPS, as well as relevant external data (market reports, competitor information). This data is stored, organized, and managed in databases and data warehouses. Its quality—accuracy, timeliness, and relevance—directly determines the value of the system’s output. The data resource is the raw material that the MIS transforms into meaningful information, making its effective governance and management critical for reliable reporting and analysis.

2. Hardware

Hardware refers to the physical technology infrastructure required to operate the MIS. This includes servers for processing and storing data, computers and workstations for user access, networking equipment (routers, switches) for internal connectivity, and data centers to house the equipment. The choice of hardware influences the system’s processing speed, storage capacity, reliability, and scalability. In modern contexts, this increasingly includes cloud infrastructure, where hardware resources are provided as a service, offering flexibility and reducing the need for large capital investments in physical assets.

3. Software

Software is the set of programs and applications that process data and generate information. This includes the Database Management System (DBMS) that organizes data, the application software for generating specific reports and dashboards, and analytical tools for data mining and querying. The software component dictates the system’s functionality, user interface, and ability to transform raw data into usable formats for managers. It acts as the “brain” of the MIS, executing the logic for summarization, comparison, and presentation.

4. Procedures

Procedures are the formalized rules and guidelines that define how the MIS is used and managed. This includes operational procedures for data entry, validation, and storage; guidelines for generating standard and ad-hoc reports; and protocols for system access, security, and backup. Clear, documented procedures ensure consistency, data integrity, and effective utilization of the system by both technical staff and end-users, turning technology into a reliable business process.

5. People

People are the most vital component, encompassing all human elements involved. This includes end-users (managers, executives) who consume the information to make decisions, technical specialists (system analysts, database administrators) who design, implement, and maintain the system, and support staff. The system’s success depends entirely on the skills, training, and acceptance of these individuals. Their ability to define information needs, interpret outputs, and act on insights determines the MIS’s ultimate value to the organization.

6. Communication Networks

Communication networks are the digital pathways that enable the flow of data between all other components. This includes Local Area Networks (LANs), Wide Area Networks (WANs), and internet connectivity. Networks allow for the collection of data from remote sources, provide access to centralized databases for distributed users, and facilitate the delivery of reports and dashboards to managers’ devices. Robust, secure networking is essential for ensuring timely, reliable, and accessible information across the organization.

7. Information Products (Output)

This component is the tangible result of the MIS—the reports, dashboards, alerts, and analyses delivered to management. These information products, such as sales summaries, performance scorecards, or budget variance reports, are tailored to support specific managerial functions. Their design—clarity, relevance, and timeliness—is critical. They represent the culmination of the entire system’s work, transforming processed data into actionable intelligence that informs planning, control, and decision-making.

8. Control and Feedback Mechanisms

A mature MIS incorporates feedback loops to monitor its own effectiveness and accuracy. Control mechanisms track whether the system is meeting managerial information needs and identify errors or gaps in data. User feedback on report relevance and system usability is collected to drive continuous improvement. This component ensures the MIS remains aligned with evolving business goals and adapts to new requirements, maintaining its role as a vital management tool.

Types of Information Systems


  1. Transaction Processing Systems (TPS): Used to record and manage day-to-day business transactions. An example is a Point of Sale (POS) system, which tracks daily sales.
  2. Management Information Systems (MIS): These systems guide middle-level managers in making semi-structured decisions. They use data from the Transaction Processing System as input.
  3. Decision Support Systems (DSS): Utilized by top-level managers for semi-structured decision-making. DSS systems receive data from the Management Information System and external sources like market forces and competitors.

Process of Management Information System (MIS):

1. Determination of Information Needs

The first step is a systematic analysis to define what information managers need to perform their roles effectively. This involves identifying key decision areas, strategic objectives, and performance indicators for different management levels. Questions like “What data is critical for inventory control?” or “Which KPIs does a sales head need weekly?” are answered. This stage aligns the MIS design directly with managerial requirements, ensuring the system delivers relevant, actionable intelligence rather than just raw data, and involves collaboration between end-users (managers) and system designers.

2. Data Collection and Input

This process involves gathering raw data from identified internal and external sources. Internally, data is sourced continuously from Transaction Processing Systems (TPS) across departments (sales, production, finance). Externally, data may be collected from market feeds, economic reports, or competitor analysis. This data is then validated and entered into the system’s databases. Accurate collection and error-free input are critical, as the quality of all subsequent information depends on the integrity of this foundational data.

3. Data Processing and Transformation

Here, the collected raw data is converted into meaningful information. This involves a series of operations: classification, sorting, calculating, summarizing, and aggregating. For instance, thousands of daily sales transactions are totaled into weekly revenue figures. Data is processed using predefined business rules and models. This transformation is the core function where disparate data points are synthesized into structured summaries, trends, and comparisons that managers can understand and use for decision-making.

4. Storage and Management of Processed Data

Processed information is organized and stored for immediate and future access. This involves managing databases or data warehouses where summarized data, historical trends, and performance metrics are retained. Effective storage ensures data integrity, security, and efficient retrieval. This stage creates an organizational memory—a repository of past performance and trends that managers can query to analyze historical patterns and support longitudinal analysis for planning.

5. Information Generation and Retrieval

In this stage, the system produces the required outputs for management. Based on scheduled needs or ad-hoc queries, the MIS retrieves stored data and formats it into standardized reports, dashboards, or graphical analyses. These outputs—such as a monthly profit & loss statement or a real-time inventory status dashboard—are tailored to the user’s role. The system must provide timely, accurate, and easily interpretable information that managers can retrieve on-demand to support their specific activities.

6. Dissemination and Distribution of Information

The generated information must be communicated effectively to the right managers at the right time. This process involves distributing reports via email, publishing them on intranet portals, or pushing alerts to mobile devices. Distribution protocols ensure that sensitive information reaches only authorized personnel. Efficient dissemination closes the loop, ensuring the intelligence produced by the MIS is delivered into the hands of decision-makers who can act upon it, thereby fulfilling the system’s primary purpose.

7. Utilization and Feedback for System Refinement

The final, cyclical stage involves managers actively using the information for planning, control, and decision-making. Their experience and the outcomes of their decisions generate critical feedback. This feedback on the information’s relevance, accuracy, timeliness, and format is communicated back to the MIS team. This input is used to continuously refine the system—adjusting data sources, processing rules, or report formats—ensuring the MIS evolves to meet changing managerial needs and remains a dynamic, valuable organizational tool.

Advantages of Management Information System (MIS):

1. Enhanced Decision-Making Efficiency

MIS transforms raw data into structured, summarized information, providing managers with a fact-based foundation for decisions. By delivering timely reports on key performance indicators (KPIs), budgets, and trends, it reduces reliance on intuition and guesswork. This leads to faster, more accurate, and confident decisions at tactical and operational levels. For example, a sales manager can quickly identify underperforming regions based on comparative reports and reallocate resources. The system minimizes uncertainty, allowing managers to focus on analysis and action rather than data collection and manual calculation.

2. Improved Operational Control and Planning

MIS serves as a vital tool for monitoring and controlling day-to-day operations. It provides regular performance reports that compare actual results against plans and budgets, highlighting variances. This enables managers to identify bottlenecks, inefficiencies, or deviations early and take corrective action promptly. Furthermore, by analyzing historical trends and current performance data, MIS supports effective short-term and medium-term planning, such as setting realistic sales targets or production schedules, ensuring resources are aligned with organizational goals.

3. Strategic Insight and Competitive Advantage

By integrating data from across the organization, MIS provides a holistic view of business performance and market position. Analysis of long-term trends, customer behavior, and operational efficiency can reveal strategic opportunities and threats. This insight helps senior management in formulating long-term strategies, such as entering new markets or discontinuing unprofitable products. A well-implemented MIS can thus become a source of sustainable competitive advantage by enabling proactive, data-driven strategy rather than reactive management.

4. Increased Organizational Efficiency and Coordination

MIS eliminates information silos by integrating data from all functional areas (finance, marketing, HR, production). This creates a single source of truth, improving coordination between departments. For instance, production can align output with sales forecasts, and procurement can plan based on inventory levels. Streamlined information flow reduces redundancy, minimizes errors, and accelerates processes. The resulting efficiency gains lower operational costs, improve resource utilization, and enhance the organization’s overall agility and responsiveness.

5. Better Communication and Collaboration

MIS acts as a centralized platform for information dissemination, standardizing communication across management levels. Reports and dashboards ensure all managers work from the same, up-to-date data set, fostering alignment and shared understanding. This transparency improves vertical and horizontal collaboration, as teams can easily access the information needed to coordinate projects and make interdependent decisions. Enhanced communication reduces conflicts stemming from misinformation and builds a more cohesive, informed organizational culture.

6. Cost Reduction and Resource Optimization

Automating the collection, processing, and reporting of management information significantly reduces administrative and clerical costs associated with manual report generation. MIS also enables data-driven resource optimization. By providing clear visibility into operations, it helps identify areas of waste, overstaffing, or underutilized assets. Managers can optimize inventory levels, streamline workflows, and improve workforce productivity, leading to direct bottom-line savings and a higher return on investment in both human and capital resources.

7. Support for Performance Management

MIS provides the objective data necessary for effective performance measurement and management. It tracks individual, departmental, and organizational KPIs, facilitating fair and transparent performance evaluations. This data supports management by objectives (MBO), helps in setting benchmarks, and identifies training or development needs. By linking performance data to outcomes, it motivates employees, aligns individual goals with corporate strategy, and creates a culture of accountability and continuous improvement.

Disadvantages of Management Information System (MIS):

1. Fast and Accurate Data Processing

Transaction Processing Systems handle a large number of business transactions quickly and without errors. They record sales, payments, payroll, and inventory updates in real time. In Indian banks and retail stores, TPS ensures every transaction is saved correctly. This reduces manual work and mistakes. Fast processing helps businesses serve customers better and keep records up to date. Accurate data also supports better reporting and decision making.

2. Improved Operational Efficiency

TPS automates routine business activities such as billing, order processing, and salary payments. This saves time and reduces paperwork. Indian companies use TPS in supermarkets, railway booking systems, and online payments. Automation allows employees to focus on more important tasks. As work becomes faster and smoother, overall business efficiency increases and operating costs reduce.

3. Better Record Keeping and Data Security

TPS stores transaction data in organized digital databases. Businesses can easily retrieve past records for audits, tax filing, and analysis. Indian firms benefit during GST reporting and financial reviews. Modern TPS also includes security features like passwords and access control to protect sensitive information. Proper record keeping improves transparency and trust.

4. Real Time Information Availability

TPS updates information instantly after every transaction. For example, when a product is sold, inventory levels change immediately. This helps managers track stock, cash flow, and customer activity in real time. Indian retail and logistics companies rely on real time data to avoid shortages and delays. Quick information supports better operational decisions.

Management Information System Role in Decision making Process:

1. Providing a Structured Factual Foundation

MIS transforms disparate, raw data from operational systems into organized, summarized information. It delivers structured reports on sales, inventory, finances, and productivity. This provides managers with a reliable, objective, and comprehensive factual base, replacing intuition or fragmented data with concrete evidence. By presenting clear metrics and historical trends, MIS eliminates ambiguity and establishes a shared truth, allowing managers to confidently frame problems and evaluate the current state of operations before proceeding with any analysis or choice.

2. Enabling Identification of Problems and Opportunities

Through routine and exception-based reporting, MIS acts as an early warning system. It highlights deviations from plans, such as a drop in regional sales, a cost overrun, or a spike in customer complaints. By systematically tracking KPIs, it helps managers identify negative trends (problems) and spot positive patterns (opportunities), such as an unexpectedly successful product line. This proactive identification ensures that decision-making is triggered by timely, data-driven insights rather than by crisis or chance, allowing for strategic intervention at the optimal moment.

3. Supporting the Generation and Evaluation of Alternatives

Once a problem or opportunity is identified, MIS aids in exploring solutions. It allows for “what-if” scenario analysis by modeling the potential outcomes of different courses of action. Managers can use historical data to simulate the impact of a price change, a new marketing spend, or a shift in production schedules. By providing predictive reports and comparative analyses, MIS helps generate viable alternatives and objectively evaluate their projected consequences on key metrics like revenue, cost, and market share, leading to more informed and rational choice selection.

4. Facilitating the Implementation of Decisions

After a decision is made, MIS plays a crucial role in translating the choice into actionable plans. It provides the detailed operational data needed to create implementation schedules, allocate budgets, and assign resources. For instance, launching a new product requires coordinated data from production capacity, inventory levels, and marketing budgets—all supplied by the MIS. By serving as the central information hub, it ensures all departments work from synchronized data, enabling clear communication of tasks and responsibilities for effective execution.

5. Enabling Monitoring, Control, and Feedback

Post-implementation, MIS is essential for tracking the results of the decision. It generates follow-up reports that measure actual performance against the expected outcomes defined during planning. This continuous monitoring allows managers to control the process, identify any implementation gaps or unforeseen issues, and make necessary mid-course corrections. The feedback loop created by this monitoring turns the decision-making process into a cycle of continuous improvement, where the results of past decisions inform and refine future ones.

error: Content is protected !!