Business Mathematics & Statistics Bangalore University B.com 3rd Semester NEP Notes

Unit 1 Commercial Arithmetic [Book]
Percentage VIEW
Cost, Profit and Selling price VIEW
Ratio Proportion VIEW
Problems on Speed and Time VIEW
Interest-Simple interest and Compound interest VIEW
Annuity VIEW


Unit 2 Theory of Equations [Book] No Update


Unit 3 Matrices and Determinants [Book] No Update


Unit 4 Measures of Central Tendency and Dispersion [Book]
Introduction Meaning and Definition, Objectives of measures of Central tendency VIEW
Types of averages: Arithmetic mean (Simple average only) VIEW
Median VIEW
Mode VIEW
Meaning and Objectives of measures of Dispersion VIEW
VIEW VIEW
Standard deviation and coefficient of Variation VIEW
Skewness VIEW VIEW
Problems on Direct method only VIEW


Unit 5 Correlation and Regression [Book]
Correlation: Meaning and definition-uses VIEW VIEW
VIEW
Karl Pearson’s coefficient of correlation (deviation from actual mean only) VIEW
Spearman’s Rank Correlation Coefficient VIEW
Regression Meaning VIEW
Regression Equations, Estimating x and y values VIEW
Finding correlation coefficient with Regression coefficient VIEW VIEW

Data, Concepts, Characteristics, and Types

Data refers to the facts, figures, observations, opinions, measurements, and information collected for the purpose of research and analysis. In business research, data provides the foundation for understanding business problems, testing hypotheses, identifying trends, and making informed decisions. Data may be collected from customers, employees, markets, organizations, government sources, reports, surveys, interviews, and observations. Properly collected and analyzed data helps researchers draw meaningful conclusions and develop evidence-based business strategies.

Characteristics of Good Data

1. Accuracy

Accuracy means that data correctly represents the actual facts, conditions, or measurements being studied. Accurate data should be free from errors, incorrect entries, duplication, and misleading information. In business research, inaccurate data can produce incorrect analysis and poor decisions. Researchers should use appropriate data collection methods, trained investigators, and proper verification procedures to improve accuracy. For example, correct sales figures help managers evaluate actual business performance. Therefore, accuracy is essential for obtaining valid and dependable research findings.

2. Reliability

Reliability refers to the consistency and dependability of data. Reliable data should produce similar results when collected repeatedly under similar conditions using appropriate methods. In business research, reliability is important because inconsistent information can lead to misleading conclusions. Researchers can improve reliability through standardized questionnaires, consistent measurement procedures, trained researchers, and appropriate sampling techniques. Reliable data enables researchers and managers to have greater confidence in research findings and supports consistent analysis, interpretation, comparison, and decision-making.

3. Relevance

Relevance means that collected data should be directly related to the research problem, objectives, and information requirements. Data that does not contribute to answering research questions may consume time and resources without providing useful insights. In business research, relevant data helps managers focus on important issues such as customer preferences, market demand, employee performance, or sales trends. Researchers should carefully identify their information requirements before collecting data. Relevant data makes research more focused, meaningful, and useful for managerial decisions.

4. Completeness

Completeness means that data should contain all the essential information required for conducting meaningful research and analysis. Missing values, incomplete responses, or gaps in important variables can affect research findings and reduce their usefulness. Researchers should design appropriate data collection instruments, monitor responses, and verify collected information to minimize missing data. Complete information provides a comprehensive understanding of the research problem. In business research, completeness helps ensure that important aspects of customers, markets, operations, or organizational performance are properly examined.

5. Timeliness

Timeliness refers to the availability of data at the right time and its suitability for representing current conditions. Data can lose its usefulness when business environments change rapidly. For example, outdated information about market demand, customer preferences, prices, or competitors may lead to inappropriate decisions. Researchers should collect and update data according to the requirements of the research problem. Timely data enables managers to respond effectively to changing market conditions, emerging opportunities, and potential threats, thereby improving decision-making.

6. Consistency

Consistency means that data should follow uniform definitions, formats, measurement units, and collection procedures throughout the research process. Inconsistent data makes comparison and analysis difficult and may produce misleading results. For example, using different definitions of customer satisfaction across departments can affect research findings. Researchers should establish standardized procedures and measurement criteria before collecting information. Consistent data allows meaningful comparisons across different periods, groups, locations, or organizations and improves the overall quality and interpretability of research results.

7. Validity

Validity refers to the extent to which data accurately measures or represents what the research intends to measure. Valid data should correspond closely to the research concepts and variables being investigated. For example, a customer satisfaction questionnaire should genuinely measure customer satisfaction rather than unrelated factors. Researchers can improve validity through suitable research designs, carefully constructed questions, appropriate measurement scales, and proper sampling. High validity ensures that research findings accurately address the research objectives and support meaningful conclusions.

8. Objectivity

Objectivity means that data should be collected and presented without personal bias, prejudice, or manipulation. Researchers should maintain neutrality throughout the processes of data collection, analysis, and interpretation. Leading questions, selective reporting, and personal opinions can influence research results and reduce their credibility. Using standardized procedures, unbiased questions, appropriate sampling, and transparent analysis helps maintain objectivity. Objective data provides a more balanced representation of the research situation and supports fair, logical, and evidence-based business decisions.

Types of Data in Business Research

1. Primary Data

Primary Data refers to information collected first-hand by the researcher specifically for a particular research study. It is obtained directly from respondents or original sources through surveys, questionnaires, interviews, observations, experiments, and focus groups. Primary data is highly relevant because the researcher designs the collection process according to specific research objectives. It provides current and detailed information but generally requires more time, cost, and effort. Businesses use primary data to understand customer preferences, employee opinions, market demand, and satisfaction levels.

Example: A company conducts a customer satisfaction survey among 500 customers to understand their opinions about product quality and service.

2. Secondary Data

Secondary Data is information that has already been collected and recorded by another person, organization, or institution for a previous or different purpose. Sources include government publications, company reports, books, journals, websites, research papers, industry reports, and databases. Secondary data is generally less expensive and quicker to obtain than primary data. However, researchers must examine its reliability, relevance, accuracy, and timeliness before using it. It is useful for understanding background information, market conditions, industry trends, and historical developments.

Example: A company studying the Indian automobile market may use government statistics and industry reports to examine vehicle sales trends over several years.

3. Qualitative Data

Qualitative Data consists of non-numerical information that describes people’s opinions, attitudes, experiences, perceptions, motivations, and behaviours. It provides detailed insights into why people think or behave in particular ways. Common methods of collecting qualitative data include in-depth interviews, focus groups, observations, and open-ended questions. This data is especially useful in exploratory research where researchers want to understand complex business and consumer issues. Although it does not primarily involve numerical measurement, it provides rich information for understanding human behaviour.

Example: A company conducts focus group discussions with customers to understand why they prefer one brand over another and what improvements they expect in the product.

4. Quantitative Data

Quantitative Data refers to information expressed in numerical or measurable form. It can be counted, measured, compared, and analyzed using statistical techniques. Examples include sales revenue, profit, market share, production quantity, customer ratings, employee turnover, and number of customers. Quantitative data is commonly collected through structured questionnaires, surveys, experiments, and business records. It helps researchers identify measurable patterns, relationships, differences, and trends and is widely used for hypothesis testing.

Example: A retailer collects data showing that monthly sales increased from ₹8 lakh to ₹10 lakh after a promotional campaign. Researchers can statistically analyze this numerical information to evaluate the campaign’s performance.

5. Discrete Data

Discrete Data consists of countable numerical values that generally occur as whole numbers. It represents separate and distinct quantities and usually cannot take every possible value within a range. Discrete data is obtained through counting rather than continuous measurement. In business research, it can be used to measure the number of employees, customers, products sold, complaints received, or orders processed. Researchers can summarize discrete data using frequency tables, percentages, charts, and statistical measures.

Example: A supermarket records the number of customers visiting each day, such as 450 customers on Monday and 520 customers on Tuesday. Since customers are counted as separate units, the information represents discrete data.

6. Continuous Data

Continuous Data refers to numerical information that can take any value within a specific range and is generally obtained through measurement. It can include decimal values and provides detailed information about measurable characteristics. Examples include income, product weight, delivery time, production time, temperature, distance, and employee working hours. Continuous data is useful for analyzing variations and relationships between measurable business variables. Researchers can apply statistical techniques to identify averages, distributions, and trends.

Example: A delivery company records the time taken to deliver orders as 25.4 minutes, 31.7 minutes, and 28.9 minutes. Since delivery time can take different values, including decimals, it represents continuous data.

7. Nominal Data

Nominal Data consists of categories or labels used to classify observations without any natural order or ranking. The categories are different from one another but cannot meaningfully be arranged as higher or lower. Nominal data is commonly used to classify brands, locations, departments, product categories, customer groups, or types of businesses. Researchers generally summarize nominal data using frequencies and percentages. It helps researchers understand the composition and characteristics of a population.

Example: A survey asks customers which mobile brand they currently use, with options such as Samsung, Apple, Xiaomi, and OnePlus. These categories represent nominal data because one brand cannot be considered naturally higher or lower than another.

8. Ordinal Data

Ordinal Data consists of categories that have a meaningful order or ranking, but the differences between categories may not be equal. It is commonly used to measure attitudes, satisfaction, preferences, performance, and perceptions. Researchers can arrange responses from lower to higher levels, but the exact numerical distance between categories cannot necessarily be established. Ordinal data is frequently collected through rating scales and questionnaires.

Example: A hotel asks guests to rate their satisfaction as Very Poor, Poor, Average, Good, or Excellent. These responses have a clear order from lower to higher satisfaction, making them ordinal data.

Plagiarism in Research

Plagiarism in Research refers to the act of using another person’s words, ideas, data, findings, concepts, or intellectual work without giving proper acknowledgment and presenting it as one’s own. It is considered a serious violation of academic integrity and research ethics. Plagiarism may occur through directly copying text, using ideas without citation, inadequate paraphrasing, or reproducing research material without permission or attribution.

Researchers should avoid plagiarism by using proper citations, references, quotations, and paraphrasing when incorporating information from other sources. Maintaining accurate records of sources during research also helps prevent accidental plagiarism. Common forms include direct plagiarism, self-plagiarism, mosaic plagiarism, and accidental plagiarism. Researchers should also ensure that data, results, and conclusions are reported honestly and that contributions of other researchers are appropriately recognized.

Plagiarism can damage a researcher’s academic reputation and credibility and may result in institutional or professional consequences. Therefore, maintaining originality, transparency, and proper acknowledgment is essential for producing ethical, credible, and trustworthy research.

Types of Plagiarism

1. Direct Plagiarism

Direct Plagiarism occurs when a researcher copies another person’s words or sentences exactly without using quotation marks and providing proper citation. It is one of the clearest forms of academic misconduct because the original author’s work is presented as the researcher’s own. Direct plagiarism can occur in research papers, assignments, reports, and publications. Researchers should use quotation marks, citations, and references whenever exact words from another source are used.

2. Mosaic Plagiarism

Mosaic Plagiarism occurs when a researcher takes phrases, expressions, or ideas from different sources and combines them with their own writing without proper acknowledgment. The resulting text may appear original but contains substantial material borrowed from other authors. It is sometimes caused by inadequate paraphrasing or poor note-taking. Researchers should carefully distinguish their own ideas from sourced information and provide appropriate citations when using material from other works.

3. Self-Plagiarism

Self-Plagiarism occurs when a researcher reuses substantial portions of their own previously published or submitted work without appropriate disclosure or acknowledgment. Although the material was originally created by the researcher, presenting previously used work as entirely new can be misleading. It may occur when researchers reuse paragraphs, data, or findings in multiple publications. Researchers should follow relevant publication policies and clearly disclose or appropriately reference previously used material.

4. Accidental Plagiarism

Accidental Plagiarism occurs unintentionally when a researcher fails to provide proper citations, references, quotation marks, or paraphrasing. It may result from careless note-taking, misunderstanding citation rules, or forgetting the source of information. Although unintentional, it can still violate academic standards. Researchers can reduce accidental plagiarism by maintaining accurate source records, learning referencing requirements, and reviewing their work carefully before submission or publication.

5. Paraphrasing Plagiarism

Paraphrasing Plagiarism occurs when a researcher changes only a few words or rearranges the sentence structure of another author’s work while keeping the original meaning and structure without proper citation. Effective paraphrasing requires expressing the idea genuinely in one’s own words and sentence structure while acknowledging the original source. Proper citation remains necessary even when the researcher does not copy the source word-for-word.

6. Source-Based Plagiarism

Source-Based Plagiarism occurs when a researcher provides incorrect, incomplete, or misleading information about sources. This may include citing a source that was not actually used, failing to cite the original author, or presenting information through an indirect source as though it came from the original source. Accurate referencing requires researchers to verify their sources and clearly identify where their information, ideas, evidence, or quotations originated.

7. Data Plagiarism

Data Plagiarism involves using another researcher’s data, tables, figures, datasets, or research results without proper acknowledgment or permission where required. Data may be copied from published studies, databases, surveys, or research reports and presented as original work. Proper attribution is essential when using existing data. Researchers should clearly identify the data source, ownership, methodology, and relevant permissions to maintain transparency and research integrity.

8. Idea Plagiarism

Idea Plagiarism occurs when a researcher uses another person’s original idea, concept, theory, argument, or research approach without giving appropriate credit. Even when the exact wording is not copied, taking an identifiable intellectual contribution without acknowledgment can constitute plagiarism. Researchers should cite the original source when using distinctive ideas or arguments. Proper attribution recognizes intellectual contributions and supports academic honesty and research credibility.

Causes of Plagiarism

1. Lack of Awareness

A major cause of plagiarism is a lack of understanding about academic integrity, citation, referencing, and paraphrasing. Some students and researchers may not know that ideas and information also require acknowledgment, even when exact words are not copied. Insufficient awareness of institutional guidelines can lead to accidental plagiarism. Proper education about research ethics, source acknowledgment, quotation practices, and referencing styles can help researchers understand and avoid plagiarism.

2. Poor Time Management

Poor Time Management can increase the likelihood of plagiarism. Researchers working under tight deadlines may copy information from websites, books, articles, or previous assignments rather than developing original writing. Limited time can also result in inadequate citation and careless paraphrasing. Effective planning, scheduling, note-taking, drafting, and reviewing can reduce last-minute pressure. Allocating sufficient time to research and writing allows researchers to properly analyze sources and produce original work.

3. Pressure for Academic Performance

Academic Pressure may encourage some individuals to engage in plagiarism to complete assignments, dissertations, publications, or research projects quickly. Pressure to obtain high grades, meet publication expectations, or demonstrate academic achievement can create incentives for inappropriate shortcuts. However, academic success should be based on original work, honest research, and proper acknowledgment. Supportive academic environments and clear ethical expectations can help reduce pressure-related misconduct.

4. Easy Access to Information

The widespread availability of information through the internet, digital libraries, websites, journals, and online databases has made copying material extremely easy. Researchers can quickly find ready-made content and may reproduce it without proper citation. Easy access itself does not cause plagiarism, but careless use of digital information can increase the risk. Researchers should develop effective source evaluation, note-taking, paraphrasing, and referencing practices when using online materials.

5. Poor Note-Taking Practices

Poor Note-Taking can cause researchers to confuse their own ideas with information obtained from sources. When copied quotations, paraphrased ideas, and personal observations are recorded without clear labels, researchers may later use source material without proper citation. Maintaining organized research notes with author names, publication details, page numbers, quotations, and personal comments helps distinguish original thinking from borrowed information and reduces accidental plagiarism.

6. Inadequate Paraphrasing Skills

Weak Paraphrasing Skills can lead researchers to reproduce the structure and wording of an original source while making only minor changes. This may result in plagiarism even when the researcher attempts to rewrite the material. Effective paraphrasing requires understanding the original idea, expressing it independently, and providing an appropriate citation. Training in academic writing, summarizing, paraphrasing, and citation can significantly reduce this problem.

7. Lack of Research Skills

Insufficient Research and Academic Writing Skills may contribute to plagiarism. Researchers who struggle to locate reliable sources, organize information, develop arguments, or write academically may depend heavily on existing material. Lack of knowledge about research methodology, referencing systems, critical thinking, and scholarly writing can increase the risk of inappropriate copying. Developing research skills helps individuals create independent arguments while using existing literature responsibly.

8. Intentional Misconduct

Sometimes plagiarism is intentional, meaning an individual knowingly presents another person’s work, ideas, or data as their own. It may be motivated by the desire to save time, obtain academic recognition, meet deadlines, or avoid the effort involved in original research. Intentional plagiarism represents a serious breach of academic integrity. Strong ethical education, institutional policies, proper supervision, and awareness of consequences can discourage deliberate misconduct.

Ways to Prevent Plagiarism

1. Use Proper Citations

Using proper citations is one of the most effective ways to prevent plagiarism. Whenever researchers use another person’s ideas, arguments, findings, data, or words, they should acknowledge the appropriate source. Citation styles such as APA, MLA, Chicago, or Harvard provide systematic methods for attribution. Researchers should follow the citation style required by their institution, journal, or research project and maintain consistency throughout their work.

2. Practice Effective Paraphrasing

Effective Paraphrasing involves expressing information from a source using genuinely original wording and sentence structure while preserving the intended meaning. Simply replacing a few words is not sufficient. Researchers should first understand the source, write the idea independently, and then compare the result with the original. Even when information is paraphrased, the original source must be cited to acknowledge the intellectual contribution.

3. Use Quotation Marks

Researchers should use quotation marks when reproducing the exact words of another author. The quotation should be accompanied by an appropriate citation and reference according to the required referencing style. Direct quotations should be used selectively and accurately. Clearly distinguishing an author’s exact words from the researcher’s own writing prevents readers from mistakenly believing that borrowed language represents original work.

4. Maintain Research Notes

Maintaining organized research notes helps researchers track the sources used during a project. Notes should clearly distinguish between direct quotations, paraphrased information, summarized ideas, and the researcher’s own thoughts. Important details such as author, title, publication date, page number, and source location should be recorded. Good note-taking reduces accidental plagiarism and makes the final referencing process easier and more accurate.

5. Prepare a Reference List

A complete Reference List identifies the sources cited in the research work. Researchers should ensure that every source cited in the text is appropriately included in the reference list and that references contain accurate bibliographic information. Consistent referencing demonstrates respect for original authors and allows readers to locate the sources. Using recognized citation guidelines helps maintain transparency, traceability, and academic integrity.

6. Use Plagiarism Detection Tools

Plagiarism Detection Tools can help researchers identify similarities between their work and existing published material. These tools compare submitted text with available databases and highlight potentially matching content. Researchers should review detected similarities carefully because matching text does not automatically prove plagiarism. Detection tools are best used as a quality-control measure alongside proper citation, paraphrasing, and ethical writing practices.

7. Develop Original Ideas

Developing Original Ideas and Arguments reduces excessive dependence on existing sources. Researchers should critically analyze previous studies, compare different viewpoints, interpret evidence, and develop their own conclusions. Existing literature should be used to support and contextualize arguments rather than simply being copied. Critical thinking, independent analysis, and proper synthesis help researchers produce meaningful original contributions while appropriately acknowledging previous scholarship.

8. Follow Academic Ethics

Following Academic Ethics provides a broader framework for preventing plagiarism. Researchers should practice honesty, transparency, responsibility, originality, and respect for intellectual property throughout the research process. Institutions should provide clear guidelines, training, supervision, and appropriate procedures for addressing misconduct. Researchers should also review their work before submission to ensure that borrowed material is properly acknowledged and that their research accurately represents their own contributions.

Consequences of Plagiarism

1. Academic Penalties

Plagiarism can result in various academic penalties depending on institutional rules and the seriousness of the violation. Students may receive reduced marks, fail an assignment, have a research project rejected, or face disciplinary procedures. Researchers and academics may also face consequences related to publications or professional responsibilities. Institutions generally consider the circumstances and applicable policies when determining appropriate action against plagiarism.

2. Loss of Academic Reputation

Plagiarism can damage an individual’s academic reputation and credibility. Students, researchers, and academics depend on trust in their work and intellectual contributions. When plagiarism is identified, teachers, institutions, publishers, or colleagues may question the originality and integrity of other work produced by the individual. Rebuilding professional credibility can be difficult because academic relationships depend heavily on honesty, accurate attribution, and responsible research practices.

3. Publication Consequences

In academic publishing, plagiarism can lead to rejection, correction, withdrawal, or retraction of research work depending on the circumstances and publication policies. Journals generally expect authors to submit original work and appropriately acknowledge previous research. If problematic material is discovered after publication, editors may take corrective action. Such outcomes can affect the researcher’s publication record and may require additional review of related research outputs.

4. Legal and Copyright Issues

Certain forms of plagiarism may create copyright concerns, particularly when protected material is reproduced without authorization or outside applicable exceptions. Copyright law and academic plagiarism are related but not identical concepts. A plagiarism case may involve institutional or ethical issues even when copyright infringement is not established. Researchers should respect copyright, licensing conditions, permissions, and attribution requirements when using text, images, datasets, tables, or other protected material.

5. Loss of Research Credibility

Plagiarism can reduce confidence in the credibility of research findings produced by an individual. If substantial portions of a study are improperly borrowed, readers may question whether the researcher’s analysis, interpretations, methodology, or conclusions are genuinely original. This can affect the perceived reliability of the research and may require further investigation. Maintaining accurate attribution and transparent research practices is therefore essential for preserving research credibility.

6. Professional Consequences

Plagiarism may have professional consequences for researchers, teachers, consultants, or other professionals whose work depends on intellectual integrity. Depending on organizational or professional rules, consequences may include disciplinary action, loss of responsibilities, or damage to professional relationships. The specific consequences vary according to the institution, employment conditions, publication policies, and seriousness of the conduct. Professional integrity requires accurate acknowledgment of others’ contributions.

7. Loss of Learning Opportunities

Plagiarism can reduce important learning opportunities because copying existing material prevents researchers and students from developing their own skills. Academic research is intended to strengthen critical thinking, writing, analysis, problem-solving, and independent reasoning. When individuals rely on copied material, they may miss the opportunity to understand the subject deeply and develop original arguments. Avoiding plagiarism encourages active learning and genuine intellectual development.

8. Damage to Institutional Integrity

Plagiarism can affect the academic integrity and reputation of educational or research institutions when repeated or serious cases occur. Universities, colleges, journals, and research organizations depend on standards of originality and ethical conduct. Effective policies, education, supervision, and fair procedures help protect institutional integrity. Maintaining strong academic standards ensures that research and educational achievements are based on honest work, responsible scholarship, and proper acknowledgment.

Normal Distribution: Importance, Central Limit Theorem

Normal distribution, or the Gaussian distribution, is a fundamental probability distribution that describes how data values are distributed symmetrically around a mean. Its graph forms a bell-shaped curve, with most data points clustering near the mean and fewer occurring as they deviate further. The curve is defined by two parameters: the mean (μ) and the standard deviation (σ), which determine its center and spread. Normal distribution is widely used in statistics, natural sciences, and social sciences for analysis and inference.

The general form of its probability density function is:

The parameter μ is the mean or expectation of the distribution (and also its median and mode), while the parameter σ is its standard deviation. The variance of the distribution is σ^2. A random variable with a Gaussian distribution is said to be normally distributed, and is called a normal deviate.

Normal distributions are important in statistics and are often used in the natural and social sciences to represent real-valued random variables whose distributions are not known. Their importance is partly due to the central limit theorem. It states that, under some conditions, the average of many samples (observations) of a random variable with finite mean and variance is itself a random variable whose distribution converges to a normal distribution as the number of samples increases. Therefore, physical quantities that are expected to be the sum of many independent processes, such as measurement errors, often have distributions that are nearly normal.

A normal distribution is sometimes informally called a bell curve. However, many other distributions are bell-shaped (such as the Cauchy, Student’s t, and logistic distributions).

Importance of Normal Distribution:

  1. Foundation of Statistical Inference

The normal distribution is central to statistical inference. Many parametric tests, such as t-tests and ANOVA, are based on the assumption that the data follows a normal distribution. This simplifies hypothesis testing, confidence interval estimation, and other analytical procedures.

  1. Real-Life Data Approximation

Many natural phenomena and datasets, such as heights, weights, IQ scores, and measurement errors, tend to follow a normal distribution. This makes it a practical and realistic model for analyzing real-world data, simplifying interpretation and analysis.

  1. Basis for Central Limit Theorem (CLT)

The normal distribution is critical in understanding the Central Limit Theorem, which states that the sampling distribution of the sample mean approaches a normal distribution as the sample size increases, regardless of the population’s actual distribution. This enables statisticians to make predictions and draw conclusions from sample data.

  1. Application in Quality Control

In industries, normal distribution is widely used in quality control and process optimization. Control charts and Six Sigma methodologies assume normality to monitor processes and identify deviations or defects effectively.

  1. Probability Calculations

The normal distribution allows for the easy calculation of probabilities for different scenarios. Its standardized form, the z-score, simplifies these calculations, making it easier to determine how data points relate to the overall distribution.

  1. Modeling Financial and Economic Data

In finance and economics, normal distribution is used to model returns, risks, and forecasts. Although real-world data often exhibit deviations, normal distribution serves as a baseline for constructing more complex models.

Central limit theorem

In probability theory, the central limit theorem (CLT) establishes that, in many situations, when independent random variables are added, their properly normalized sum tends toward a normal distribution (informally a bell curve) even if the original variables themselves are not normally distributed. The theorem is a key concept in probability theory because it implies that probabilistic and statistical methods that work for normal distributions can be applicable to many problems involving other types of distributions. This theorem has seen many changes during the formal development of probability theory. Previous versions of the theorem date back to 1810, but in its modern general form, this fundamental result in probability theory was precisely stated as late as 1920, thereby serving as a bridge between classical and modern probability theory.

Characteristics Fitting a Normal Distribution

Poisson Distribution: Importance Conditions Constants, Fitting of Poisson Distribution

Poisson distribution is a probability distribution used to model the number of events occurring within a fixed interval of time, space, or other dimensions, given that these events occur independently and at a constant average rate.

Importance

  1. Modeling Rare Events: Used to model the probability of rare events, such as accidents, machine failures, or phone call arrivals.
  2. Applications in Various Fields: Applicable in business, biology, telecommunications, and reliability engineering.
  3. Simplifies Complex Processes: Helps analyze situations with numerous trials and low probability of success per trial.
  4. Foundation for Queuing Theory: Forms the basis for queuing models used in service and manufacturing industries.
  5. Approximation of Binomial Distribution: When the number of trials is large, and the probability of success is small, Poisson distribution approximates the binomial distribution.

Conditions for Poisson Distribution

  1. Independence: Events must occur independently of each other.
  2. Constant Rate: The average rate (λ) of occurrence is constant over time or space.
  3. Non-Simultaneous Events: Two events cannot occur simultaneously within the defined interval.
  4. Fixed Interval: The observation is within a fixed time, space, or other defined intervals.

Constants

  1. Mean (λ): Represents the expected number of events in the interval.
  2. Variance (λ): Equal to the mean, reflecting the distribution’s spread.
  3. Skewness: The distribution is skewed to the right when λ is small and becomes symmetric as λ increases.
  4. Probability Mass Function (PMF): P(X = k) = [e^−λ*λ^k] / k!, Where is the number of occurrences, is the base of the natural logarithm, and λ is the mean.

Fitting of Poisson Distribution

When a Poisson distribution is to be fitted to an observed data the following procedure is adopted:

Binomial Distribution: Importance Conditions, Constants

The binomial distribution is a probability distribution that summarizes the likelihood that a value will take one of two independent values under a given set of parameters or assumptions. The underlying assumptions of the binomial distribution are that there is only one outcome for each trial, that each trial has the same probability of success, and that each trial is mutually exclusive, or independent of each other.

In probability theory and statistics, the binomial distribution with parameters n and p is the discrete probability distribution of the number of successes in a sequence of n independent experiments, each asking a yes, no question, and each with its own Boolean-valued outcome: success (with probability p) or failure (with probability q = 1 − p). A single success/failure experiment is also called a Bernoulli trial or Bernoulli experiment, and a sequence of outcomes is called a Bernoulli process; for a single trial, i.e., n = 1, the binomial distribution is a Bernoulli distribution. The binomial distribution is the basis for the popular binomial test of statistical significance.

The binomial distribution is frequently used to model the number of successes in a sample of size n drawn with replacement from a population of size N. If the sampling is carried out without replacement, the draws are not independent and so the resulting distribution is a hypergeometric distribution, not a binomial one. However, for N much larger than n, the binomial distribution remains a good approximation, and is widely used

The binomial distribution is a common discrete distribution used in statistics, as opposed to a continuous distribution, such as the normal distribution. This is because the binomial distribution only counts two states, typically represented as 1 (for a success) or 0 (for a failure) given a number of trials in the data. The binomial distribution, therefore, represents the probability for x successes in n trials, given a success probability p for each trial.

Binomial distribution summarizes the number of trials, or observations when each trial has the same probability of attaining one particular value. The binomial distribution determines the probability of observing a specified number of successful outcomes in a specified number of trials.

The binomial distribution is often used in social science statistics as a building block for models for dichotomous outcome variables, like whether a Republican or Democrat will win an upcoming election or whether an individual will die within a specified period of time, etc.

Importance

For example, adults with allergies might report relief with medication or not, children with a bacterial infection might respond to antibiotic therapy or not, adults who suffer a myocardial infarction might survive the heart attack or not, a medical device such as a coronary stent might be successfully implanted or not. These are just a few examples of applications or processes in which the outcome of interest has two possible values (i.e., it is dichotomous). The two outcomes are often labeled “success” and “failure” with success indicating the presence of the outcome of interest. Note, however, that for many medical and public health questions the outcome or event of interest is the occurrence of disease, which is obviously not really a success. Nevertheless, this terminology is typically used when discussing the binomial distribution model. As a result, whenever using the binomial distribution, we must clearly specify which outcome is the “success” and which is the “failure”.

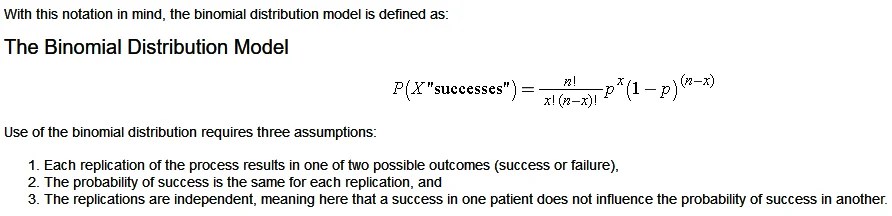
The binomial distribution model allows us to compute the probability of observing a specified number of “successes” when the process is repeated a specific number of times (e.g., in a set of patients) and the outcome for a given patient is either a success or a failure. We must first introduce some notation which is necessary for the binomial distribution model.

First, we let “n” denote the number of observations or the number of times the process is repeated, and “x” denotes the number of “successes” or events of interest occurring during “n” observations. The probability of “success” or occurrence of the outcome of interest is indicated by “p”.

The binomial equation also uses factorials. In mathematics, the factorial of a non-negative integer k is denoted by k!, which is the product of all positive integers less than or equal to k. For example,

  • 4! = 4 x 3 x 2 x 1 = 24,
  • 2! = 2 x 1 = 2,
  • 1!=1.
  • There is one special case, 0! = 1.

Conditions

  • The number of observations n is fixed.
  • Each observation is independent.
  • Each observation represents one of two outcomes (“success” or “failure”).
  • The probability of “success” p is the same for each outcome

Constants

Fitting of Binomial Distribution

Fitting of probability distribution to a series of observed data helps to predict the probability or to forecast the frequency of occurrence of the required variable in a certain desired interval.

To fit any theoretical distribution, one should know its parameters and probability distribution. Parameters of Binomial distribution are n and p. Once p and n are known, binomial probabilities for different random events and the corresponding expected frequencies can be computed. From the given data we can get n by inspection. For binomial distribution, we know that mean is equal to np hence we can estimate p as = mean/n. Thus, with these n and p one can fit the binomial distribution.

There are many probability distributions of which some can be fitted more closely to the observed frequency of the data than others, depending on the characteristics of the variables. Therefore, one needs to select a distribution that suits the data well.

Important Terminologies: Variable, Quantitative Variable, Qualitative Variable, Discrete Variable, Continuous Variable, Dependent Variable, Independent Variable, Frequency, Class Interval, Tally Bar

Important Terminologies:

  • Variable:

Variable is any characteristic, number, or quantity that can be measured or quantified. It can take on different values, which may vary across individuals, objects, or conditions, and is essential in data analysis for observing relationships and patterns.

  • Quantitative Variable:

Quantitative variable is a variable that is measured in numerical terms, such as age, weight, or income. It represents quantities and can be used for mathematical operations, making it suitable for statistical analysis.

  • Qualitative Variable:

Qualitative variable represents categories or attributes, rather than numerical values. Examples include gender, color, or occupation. These variables are non-numeric and are often used in classification and descriptive analysis.

  • Discrete Variable:

Discrete variable is a type of quantitative variable that takes distinct, separate values. These values are countable and cannot take on intermediate values. For example, the number of children in a family is a discrete variable.

  • Continuous Variable:

Continuous variable is a quantitative variable that can take an infinite number of values within a given range. These variables can have decimals or fractions. Examples include height, temperature, or time.

  • Dependent Variable:

Dependent variable is the outcome or response variable that is being measured in an experiment or study. Its value depends on the changes in one or more independent variables. It is the variable of interest in hypothesis testing.

  • Independent Variable:

An independent variable is the variable that is manipulated or controlled in an experiment. It is used to observe its effect on the dependent variable. For example, in a study on plant growth, the amount of water given would be the independent variable.

  • Frequency:

Frequency refers to the number of times a particular value or category occurs in a dataset. It is used in statistical analysis to summarize the distribution of data points within various categories or intervals.

  • Class Interval:

A class interval is a range of values within which data points fall in grouped data. It is commonly used in frequency distributions to organize data into specific ranges, such as “0-10,” “11-20,” etc.

  • Tally Bar:

A tally bar is a method of recording data frequency by using vertical lines. Every group of five tallies (four vertical lines and a fifth diagonal line) represents five occurrences, helping to visually track counts in surveys or experiments.

Important Terminologies in Statistics: Data, Raw Data, Primary Data, Secondary Data, Population, Census, Survey, Sample Survey, Sampling, Parameter, Unit, Variable, Attribute, Frequency, Seriation, Individual, Discrete and Continuous

Statistics is the branch of mathematics that involves the collection, analysis, interpretation, presentation, and organization of data. It helps in drawing conclusions and making decisions based on data patterns, trends, and relationships. Statistics uses various methods such as probability theory, sampling, and hypothesis testing to summarize data and make predictions. It is widely applied across fields like economics, medicine, social sciences, business, and engineering to inform decisions and solve real-world problems.

1. Data

Data is information collected for analysis, interpretation, and decision-making. It can be qualitative (descriptive, such as color or opinions) or quantitative (numerical, such as age or income). Data serves as the foundation for statistical studies, enabling insights into patterns, trends, and relationships.

2. Raw Data

Raw data refers to unprocessed or unorganized information collected from observations or experiments. It is the initial form of data, often messy and requiring cleaning or sorting for meaningful analysis. Examples include survey responses or experimental results.

3. Primary Data

Primary data is original information collected directly by a researcher for a specific purpose. It is firsthand and authentic, obtained through methods like surveys, experiments, or interviews. Primary data ensures accuracy and relevance to the study but can be time-consuming to collect.

4. Secondary Data

Secondary data is pre-collected information used by researchers for analysis. It includes published reports, government statistics, and historical data. Secondary data saves time and resources but may lack relevance or accuracy for specific studies compared to primary data.

5. Population

A population is the entire group of individuals, items, or events that share a common characteristic and are the subject of a study. It includes every possible observation or unit, such as all students in a school or citizens in a country.

6. Census

A census involves collecting data from every individual or unit in a population. It provides comprehensive and accurate information but requires significant resources and time. Examples include national population censuses conducted by governments.

7. Survey

A survey gathers information from respondents using structured tools like questionnaires or interviews. It helps collect opinions, behaviors, or characteristics. Surveys are versatile and widely used in research, marketing, and public policy analysis.

8. Sample Survey

A sample survey collects data from a representative subset of the population. It saves time and costs while providing insights that can generalize to the entire population, provided the sampling method is unbiased and rigorous.

9. Sampling

Sampling is the process of selecting a portion of the population for study. It ensures efficiency and feasibility in data collection. Sampling methods include random, stratified, and cluster sampling, each suited to different study designs.

10. Parameter

A parameter is a measurable characteristic that describes a population, such as the mean, median, or standard deviation. Unlike a statistic, which pertains to a sample, a parameter is specific to the entire population.

11. Unit

A unit is an individual entity in a population or sample being studied. It can represent a person, object, transaction, or observation. Each unit contributes to the dataset, forming the basis for analysis.

12. Variable

A variable is a characteristic or property that can change among individuals or items. It can be quantitative (e.g., age, weight) or qualitative (e.g., color, gender). Variables are the focus of statistical analysis to study relationships and trends.

13. Attribute

An attribute is a qualitative feature that describes a characteristic of a unit. Attributes are non-measurable but observable, such as eye color, marital status, or type of vehicle.

14. Frequency

Frequency represents how often a specific value or category appears in a dataset. It is key in descriptive statistics, helping to summarize and visualize data patterns through tables, histograms, or frequency distributions.

15. Seriation

Seriation is the arrangement of data in sequential or logical order, such as ascending or descending by size, date, or importance. It aids in identifying patterns and organizing datasets for analysis.

16. Individual

An individual is a single member or unit of the population or sample being analyzed. It is the smallest element for data collection and analysis, such as a person in a demographic study or a product in a sales dataset.

17. Discrete Variable

A discrete variable takes specific, separate values, often integers. It is countable and cannot assume fractional values, such as the number of employees in a company or defective items in a batch.

18. Continuous Variable

A continuous variable can take any value within a range and represents measurable quantities. Examples include temperature, height, and time. Continuous variables are essential for analyzing trends and relationships in datasets.

Perquisites of Good Classification of Data

Good classification of data is essential for organizing, analyzing, and interpreting the data effectively. Proper classification helps in understanding the structure and relationships within the data, enabling informed decision-making.

1. Clear Objective

Good classification should have a clear objective, ensuring that the classification scheme serves a specific purpose. It should be aligned with the goal of the study, whether it’s identifying trends, comparing categories, or finding patterns in the data. This helps in determining which variables or categories should be included and how they should be grouped.

2. Homogeneity within Classes

Each class or category within the classification should contain items or data points that are similar to each other. This homogeneity within the classes allows for better analysis and comparison. For example, when classifying people by age, individuals within a particular age group should share certain characteristics related to that age range, ensuring that each class is internally consistent.

3. Heterogeneity between Classes

While homogeneity is crucial within classes, there should be noticeable differences between the various classes. A good classification scheme should maximize the differences between categories, ensuring that each group represents a distinct set of data. This helps in making meaningful distinctions and drawing useful comparisons between groups.

4. Exhaustiveness

Good classification system must be exhaustive, meaning that it should cover all possible data points in the dataset. There should be no omission, and every item must fit into one and only one class. Exhaustiveness ensures that the classification scheme provides a complete understanding of the dataset without leaving any data unclassified.

5. Mutually Exclusive

Classes should be mutually exclusive, meaning that each data point can belong to only one class. This avoids ambiguity and ensures clarity in analysis. For example, if individuals are classified by age group, someone who is 25 years old should only belong to one age class (such as 20-30 years), preventing overlap and confusion.

6. Simplicity

Good classification should be simple and easy to understand. The classification categories should be well-defined and not overly complicated. Simplicity ensures that the classification scheme is accessible and can be easily used for analysis by various stakeholders, from researchers to policymakers. Overly complex classification schemes may lead to confusion and errors.

7. Flexibility

Good classification system should be flexible enough to accommodate new data or changing circumstances. As new categories or data points emerge, the classification scheme should be adaptable without requiring a complete overhaul. Flexibility allows the classification to remain relevant and useful over time, particularly in dynamic fields like business or technology.

8. Consistency

Consistency in classification is essential for maintaining reliability in data analysis. A good classification system ensures that the same criteria are applied uniformly across all classes. For example, if geographical regions are being classified, the same boundaries and criteria should be consistently applied to avoid confusion or inconsistency in reporting.

9. Appropriateness

Good classification should be appropriate for the type of data being analyzed. The classification scheme should fit the nature of the data and the specific objectives of the analysis. Whether classifying data by geographical location, age, or income, the scheme should be meaningful and suited to the research question, ensuring that it provides valuable insights.

Quantitative and Qualitative Classification of Data

Data refers to raw, unprocessed facts and figures that are collected for analysis and interpretation. It can be qualitative (descriptive, like colors or opinions) or quantitative (numerical, like age or sales figures). Data is the foundation of statistics and research, providing the basis for drawing conclusions, making decisions, and discovering patterns or trends. It can come from various sources such as surveys, experiments, or observations. Proper organization and analysis of data are crucial for extracting meaningful insights and informing decisions across various fields.

Quantitative Classification of Data:

Quantitative classification of data involves grouping data based on numerical values or measurable quantities. It is used to organize continuous or discrete data into distinct classes or intervals to facilitate analysis. The data can be categorized using methods such as frequency distributions, where values are grouped into ranges (e.g., 0-10, 11-20) or by specific numerical characteristics like age, income, or height. This classification helps in summarizing large datasets, identifying patterns, and conducting statistical analysis such as finding the mean, median, or mode. It enables clearer insights and easier comparisons of quantitative data across different categories.

Features of Quantitative Classification of Data:

  • Based on Numerical Data

Quantitative classification specifically deals with numerical data, such as measurements, counts, or any variable that can be expressed in numbers. Unlike qualitative data, which deals with categories or attributes, quantitative classification groups data based on values like height, weight, income, or age. This classification method is useful for data that can be measured and involves identifying patterns in numerical values across different ranges.

  • Division into Classes or Intervals

In quantitative classification, data is often grouped into classes or intervals to make analysis easier. These intervals help in summarizing a large set of data and enable quick comparisons. For example, when classifying income levels, data can be grouped into intervals such as “0-10,000,” “10,001-20,000,” etc. The goal is to reduce the complexity of individual data points by organizing them into manageable segments, making it easier to observe trends and patterns.

  • Class Limits

Each class in a quantitative classification has defined class limits, which represent the range of values that belong to that class. For example, in the case of age, a class may be defined with the limits 20-30, where the class includes all data points between 20 and 30 (inclusive). The lower and upper limits are crucial for ensuring that data is classified consistently and correctly into appropriate ranges.

  • Frequency Distribution

Frequency distribution is a key feature of quantitative classification. It refers to how often each class or interval appears in a dataset. By organizing data into classes and counting the number of occurrences in each class, frequency distributions provide insights into the spread of the data. This helps in identifying which ranges or intervals contain the highest concentration of values, allowing for more targeted analysis.

  • Continuous and Discrete Data

Quantitative classification can be applied to both continuous and discrete data. Continuous data, like height or temperature, can take any value within a range and is often classified into intervals. Discrete data, such as the number of people in a group or items sold, involves distinct, countable values. Both types of quantitative data are classified differently, but the underlying principle of grouping into classes remains the same.

  • Use of Central Tendency Measures

Quantitative classification often involves calculating measures of central tendency, such as the mean, median, and mode, for each class or interval. These measures provide insights into the typical or average values within each class. For example, by calculating the average income within specific income brackets, researchers can better understand the distribution of income across the population.

  • Graphical Representation

Quantitative classification is often complemented by graphical tools such as histograms, bar charts, and frequency polygons. These visual representations provide a clear view of how data is distributed across different classes or intervals, making it easier to detect trends, outliers, and patterns. Graphs also help in comparing the frequencies of different intervals, enhancing the understanding of the dataset.

Qualitative Classification of Data:

Qualitative classification of data involves grouping data based on non-numerical characteristics or attributes. This classification is used for categorical data, where the values represent categories or qualities rather than measurable quantities. Examples include classifying individuals by gender, occupation, marital status, or color. The data is typically organized into distinct groups or classes without any inherent order or ranking. Qualitative classification allows researchers to analyze patterns, relationships, and distributions within different categories, making it easier to draw comparisons and identify trends. It is often used in fields such as social sciences, marketing, and psychology for descriptive analysis.

Features of  Qualitative Classification of Data:

  • Based on Categories or Attributes

Qualitative classification deals with data that is based on categories or attributes, such as gender, occupation, religion, or color. Unlike quantitative data, which is measured in numerical values, qualitative data involves sorting or grouping items into distinct categories based on shared qualities or characteristics. This type of classification is essential for analyzing data that does not have a numerical relationship.

  • No Specific Order or Ranking

In qualitative classification, the categories do not have a specific order or ranking. For instance, when classifying individuals by their profession (e.g., teacher, doctor, engineer), the categories do not imply any hierarchy or ranking order. The lack of a natural sequence or order distinguishes qualitative classification from ordinal data, which involves categories with inherent ranking (e.g., low, medium, high). The focus is on grouping items based on their similarity in attributes.

  • Mutual Exclusivity

Each data point in qualitative classification must belong to one and only one category, ensuring mutual exclusivity. For example, an individual cannot simultaneously belong to both “Male” and “Female” categories in a gender classification scheme. This feature helps to avoid overlap and ambiguity in the classification process. Ensuring mutual exclusivity is crucial for clear analysis and accurate data interpretation.

  • Exhaustiveness

Qualitative classification should be exhaustive, meaning that all possible categories are covered. Every data point should fit into one of the predefined categories. For instance, if classifying by marital status, categories like “Single,” “Married,” “Divorced,” and “Widowed” must encompass all possible marital statuses within the dataset. Exhaustiveness ensures no data is left unclassified, making the analysis complete and comprehensive.

  • Simplicity and Clarity

A good qualitative classification should be simple, clear, and easy to understand. The categories should be well-defined, and the criteria for grouping data should be straightforward. Complexity and ambiguity in categorization can lead to confusion, misinterpretation, or errors in analysis. Simple and clear classification schemes make the data more accessible and improve the quality of research and reporting.

  • Flexibility

Qualitative classification is flexible and can be adapted as new categories or attributes emerge. For example, in a study of professions, new job titles or fields may develop over time, and the classification system can be updated to include these new categories. Flexibility in qualitative classification allows researchers to keep the data relevant and reflective of changes in society, industry, or other fields of interest.

  • Focus on Descriptive Analysis

Qualitative classification primarily focuses on descriptive analysis, which involves summarizing and organizing data into meaningful categories. It is used to explore patterns and relationships within the data, often through qualitative techniques such as thematic analysis or content analysis. The goal is to gain insights into the characteristics or behaviors of individuals, groups, or phenomena rather than making quantitative comparisons.

error: Content is protected !!