Data Summarization, Need

Data Summarization is the process of condensing a large dataset into a simpler, more understandable form, highlighting key information. It involves organizing and presenting data through descriptive measures such as mean, median, mode, range, and standard deviation, as well as graphical representations like charts, tables, and graphs. Data summarization provides insights into central tendency, dispersion, and data distribution patterns. Techniques like frequency distributions and cross-tabulations help identify relationships and trends within data. This concept is crucial for effective decision-making in business, enabling managers to interpret data quickly, draw conclusions, and make informed decisions without delving into raw datasets.

Need of Data Summarization:

  • Simplification of Large Datasets

In today’s data-driven world, businesses and organizations deal with massive amounts of data. Raw data is often overwhelming and challenging to analyze. Summarization condenses this complexity into manageable information, enabling users to focus on significant trends and patterns.

  • Facilitates Quick Decision-Making

Managers and decision-makers require timely insights to make informed choices. Summarized data provides a snapshot of key information, enabling faster evaluation of situations and reducing the time needed for data interpretation.

  • Identifying Trends and Patterns

Through summarization techniques such as graphical representations and descriptive statistics, businesses can identify trends and correlations. For instance, sales data can reveal seasonal trends or consumer preferences, aiding in strategic planning.

  • Improves Communication and Reporting

Effective communication of data insights to stakeholders, including team members, investors, and clients, is critical. Summarized data presented in charts, tables, or dashboards makes complex information accessible and comprehensible to a non-technical audience.

  • Supports Decision Accuracy

Summarized data reduces the risk of errors in interpretation by providing clear and focused insights. This accuracy is vital for making evidence-based decisions, minimizing the chances of bias or misjudgment.

  • Enhances Data Comparability

Data summarization facilitates comparisons between different datasets, time periods, or groups. For example, comparing summarized financial performance metrics across quarters allows organizations to assess growth and address underperformance.

  • Reduces Storage and Processing Costs

Storing and processing raw data can be resource-intensive. Summarized data requires less storage space and computational power, making it a cost-effective approach for data management, especially in large-scale systems.

  • Aids in Forecasting and Predictive Analysis

Summarized data serves as the foundation for predictive models and forecasting. By analyzing summarized historical data, organizations can anticipate future outcomes, such as demand trends, market fluctuations, or financial projections.

P2 Business Statistics BBA NEP 2024-25 1st Semester Notes

Unit 1
Data Summarization VIEW
Significance of Statistics in Business Decision Making VIEW
Data and Information VIEW
Classification of Data VIEW
Tabulation of Data VIEW
Frequency Distribution VIEW
Measures of Central Tendency: VIEW
Mean VIEW
Median VIEW
Mode VIEW
Measures of Dispersion: VIEW
Range VIEW
Mean Deviation and Standard Deviation VIEW
Unit 2
Correlation, Significance of Correlation, Types of Correlation VIEW
Scatter Diagram Method VIEW
Karl Pearson Coefficient of Correlation and Spearman Rank Correlation Coefficient VIEW
Regression Introduction VIEW
Regression Lines and Equations and Regression Coefficients VIEW
Unit 3
Probability: Concepts in Probability, Laws of Probability, Sample Space, Independent Events, Mutually Exclusive Events VIEW
Conditional Probability VIEW
Bayes’ Theorem VIEW
Theoretical Probability Distributions:
Binominal Distribution VIEW
Poisson Distribution VIEW
Normal Distribution VIEW
Unit 4
Sampling Distributions and Significance VIEW
Hypothesis Testing, Concept and Formulation, Types VIEW
Hypothesis Testing Process VIEW
Z-Test, T-Test VIEW
Simple Hypothesis Testing Problems
Type-I and Type-II Errors VIEW

Normal Distribution: Importance, Central Limit Theorem

Normal distribution, or the Gaussian distribution, is a fundamental probability distribution that describes how data values are distributed symmetrically around a mean. Its graph forms a bell-shaped curve, with most data points clustering near the mean and fewer occurring as they deviate further. The curve is defined by two parameters: the mean (μ) and the standard deviation (σ), which determine its center and spread. Normal distribution is widely used in statistics, natural sciences, and social sciences for analysis and inference.

The general form of its probability density function is:

The parameter μ is the mean or expectation of the distribution (and also its median and mode), while the parameter σ is its standard deviation. The variance of the distribution is σ^2. A random variable with a Gaussian distribution is said to be normally distributed, and is called a normal deviate.

Normal distributions are important in statistics and are often used in the natural and social sciences to represent real-valued random variables whose distributions are not known. Their importance is partly due to the central limit theorem. It states that, under some conditions, the average of many samples (observations) of a random variable with finite mean and variance is itself a random variable whose distribution converges to a normal distribution as the number of samples increases. Therefore, physical quantities that are expected to be the sum of many independent processes, such as measurement errors, often have distributions that are nearly normal.

A normal distribution is sometimes informally called a bell curve. However, many other distributions are bell-shaped (such as the Cauchy, Student’s t, and logistic distributions).

Importance of Normal Distribution:

  1. Foundation of Statistical Inference

The normal distribution is central to statistical inference. Many parametric tests, such as t-tests and ANOVA, are based on the assumption that the data follows a normal distribution. This simplifies hypothesis testing, confidence interval estimation, and other analytical procedures.

  1. Real-Life Data Approximation

Many natural phenomena and datasets, such as heights, weights, IQ scores, and measurement errors, tend to follow a normal distribution. This makes it a practical and realistic model for analyzing real-world data, simplifying interpretation and analysis.

  1. Basis for Central Limit Theorem (CLT)

The normal distribution is critical in understanding the Central Limit Theorem, which states that the sampling distribution of the sample mean approaches a normal distribution as the sample size increases, regardless of the population’s actual distribution. This enables statisticians to make predictions and draw conclusions from sample data.

  1. Application in Quality Control

In industries, normal distribution is widely used in quality control and process optimization. Control charts and Six Sigma methodologies assume normality to monitor processes and identify deviations or defects effectively.

  1. Probability Calculations

The normal distribution allows for the easy calculation of probabilities for different scenarios. Its standardized form, the z-score, simplifies these calculations, making it easier to determine how data points relate to the overall distribution.

  1. Modeling Financial and Economic Data

In finance and economics, normal distribution is used to model returns, risks, and forecasts. Although real-world data often exhibit deviations, normal distribution serves as a baseline for constructing more complex models.

Central limit theorem

In probability theory, the central limit theorem (CLT) establishes that, in many situations, when independent random variables are added, their properly normalized sum tends toward a normal distribution (informally a bell curve) even if the original variables themselves are not normally distributed. The theorem is a key concept in probability theory because it implies that probabilistic and statistical methods that work for normal distributions can be applicable to many problems involving other types of distributions. This theorem has seen many changes during the formal development of probability theory. Previous versions of the theorem date back to 1810, but in its modern general form, this fundamental result in probability theory was precisely stated as late as 1920, thereby serving as a bridge between classical and modern probability theory.

Characteristics Fitting a Normal Distribution

Poisson Distribution: Importance Conditions Constants, Fitting of Poisson Distribution

Poisson distribution is a probability distribution used to model the number of events occurring within a fixed interval of time, space, or other dimensions, given that these events occur independently and at a constant average rate.

Importance

  1. Modeling Rare Events: Used to model the probability of rare events, such as accidents, machine failures, or phone call arrivals.
  2. Applications in Various Fields: Applicable in business, biology, telecommunications, and reliability engineering.
  3. Simplifies Complex Processes: Helps analyze situations with numerous trials and low probability of success per trial.
  4. Foundation for Queuing Theory: Forms the basis for queuing models used in service and manufacturing industries.
  5. Approximation of Binomial Distribution: When the number of trials is large, and the probability of success is small, Poisson distribution approximates the binomial distribution.

Conditions for Poisson Distribution

  1. Independence: Events must occur independently of each other.
  2. Constant Rate: The average rate (λ) of occurrence is constant over time or space.
  3. Non-Simultaneous Events: Two events cannot occur simultaneously within the defined interval.
  4. Fixed Interval: The observation is within a fixed time, space, or other defined intervals.

Constants

  1. Mean (λ): Represents the expected number of events in the interval.
  2. Variance (λ): Equal to the mean, reflecting the distribution’s spread.
  3. Skewness: The distribution is skewed to the right when λ is small and becomes symmetric as λ increases.
  4. Probability Mass Function (PMF): P(X = k) = [e^−λ*λ^k] / k!, Where is the number of occurrences, is the base of the natural logarithm, and λ is the mean.

Fitting of Poisson Distribution

When a Poisson distribution is to be fitted to an observed data the following procedure is adopted:

Binomial Distribution: Importance Conditions, Constants

The binomial distribution is a probability distribution that summarizes the likelihood that a value will take one of two independent values under a given set of parameters or assumptions. The underlying assumptions of the binomial distribution are that there is only one outcome for each trial, that each trial has the same probability of success, and that each trial is mutually exclusive, or independent of each other.

In probability theory and statistics, the binomial distribution with parameters n and p is the discrete probability distribution of the number of successes in a sequence of n independent experiments, each asking a yes, no question, and each with its own Boolean-valued outcome: success (with probability p) or failure (with probability q = 1 − p). A single success/failure experiment is also called a Bernoulli trial or Bernoulli experiment, and a sequence of outcomes is called a Bernoulli process; for a single trial, i.e., n = 1, the binomial distribution is a Bernoulli distribution. The binomial distribution is the basis for the popular binomial test of statistical significance.

The binomial distribution is frequently used to model the number of successes in a sample of size n drawn with replacement from a population of size N. If the sampling is carried out without replacement, the draws are not independent and so the resulting distribution is a hypergeometric distribution, not a binomial one. However, for N much larger than n, the binomial distribution remains a good approximation, and is widely used

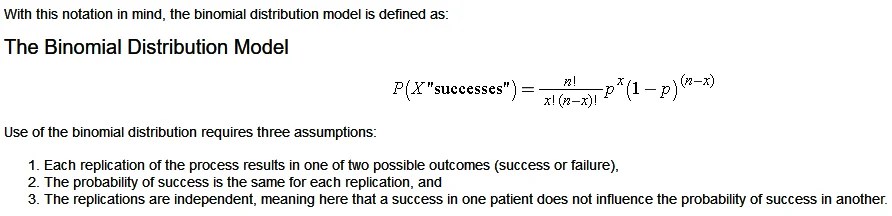
The binomial distribution is a common discrete distribution used in statistics, as opposed to a continuous distribution, such as the normal distribution. This is because the binomial distribution only counts two states, typically represented as 1 (for a success) or 0 (for a failure) given a number of trials in the data. The binomial distribution, therefore, represents the probability for x successes in n trials, given a success probability p for each trial.

Binomial distribution summarizes the number of trials, or observations when each trial has the same probability of attaining one particular value. The binomial distribution determines the probability of observing a specified number of successful outcomes in a specified number of trials.

The binomial distribution is often used in social science statistics as a building block for models for dichotomous outcome variables, like whether a Republican or Democrat will win an upcoming election or whether an individual will die within a specified period of time, etc.

Importance

For example, adults with allergies might report relief with medication or not, children with a bacterial infection might respond to antibiotic therapy or not, adults who suffer a myocardial infarction might survive the heart attack or not, a medical device such as a coronary stent might be successfully implanted or not. These are just a few examples of applications or processes in which the outcome of interest has two possible values (i.e., it is dichotomous). The two outcomes are often labeled “success” and “failure” with success indicating the presence of the outcome of interest. Note, however, that for many medical and public health questions the outcome or event of interest is the occurrence of disease, which is obviously not really a success. Nevertheless, this terminology is typically used when discussing the binomial distribution model. As a result, whenever using the binomial distribution, we must clearly specify which outcome is the “success” and which is the “failure”.

The binomial distribution model allows us to compute the probability of observing a specified number of “successes” when the process is repeated a specific number of times (e.g., in a set of patients) and the outcome for a given patient is either a success or a failure. We must first introduce some notation which is necessary for the binomial distribution model.

First, we let “n” denote the number of observations or the number of times the process is repeated, and “x” denotes the number of “successes” or events of interest occurring during “n” observations. The probability of “success” or occurrence of the outcome of interest is indicated by “p”.

The binomial equation also uses factorials. In mathematics, the factorial of a non-negative integer k is denoted by k!, which is the product of all positive integers less than or equal to k. For example,

  • 4! = 4 x 3 x 2 x 1 = 24,
  • 2! = 2 x 1 = 2,
  • 1!=1.
  • There is one special case, 0! = 1.

Conditions

  • The number of observations n is fixed.
  • Each observation is independent.
  • Each observation represents one of two outcomes (“success” or “failure”).
  • The probability of “success” p is the same for each outcome

Constants

Fitting of Binomial Distribution

Fitting of probability distribution to a series of observed data helps to predict the probability or to forecast the frequency of occurrence of the required variable in a certain desired interval.

To fit any theoretical distribution, one should know its parameters and probability distribution. Parameters of Binomial distribution are n and p. Once p and n are known, binomial probabilities for different random events and the corresponding expected frequencies can be computed. From the given data we can get n by inspection. For binomial distribution, we know that mean is equal to np hence we can estimate p as = mean/n. Thus, with these n and p one can fit the binomial distribution.

There are many probability distributions of which some can be fitted more closely to the observed frequency of the data than others, depending on the characteristics of the variables. Therefore, one needs to select a distribution that suits the data well.

Hypothesis Meaning, Nature, Significance, Null Hypothesis & Alternative Hypothesis

Hypothesis is a proposed explanation or assumption made on the basis of limited evidence, serving as a starting point for further investigation. In research, it acts as a predictive statement that can be tested through study and experimentation. A good hypothesis clearly defines the relationship between variables and provides direction to the research process. It can be formulated as a positive assertion, a negative assertion, or a question. Hypotheses help researchers focus their study, collect relevant data, and analyze outcomes systematically. If supported by evidence, a hypothesis strengthens theories; if rejected, it helps refine or redirect the research.

Nature of Hypothesis:

  • Predictive Nature

A hypothesis predicts the possible outcome of a research study. It forecasts the relationship between two or more variables based on prior knowledge, observations, or theories. Through prediction, the researcher sets a direction for investigation and frames experiments accordingly. The predictive nature helps in formulating tests and procedures that validate or invalidate the assumptions. By predicting outcomes, a hypothesis serves as a guiding tool for collecting and analyzing data systematically in the research process.

  • Testable and Verifiable

A fundamental nature of a hypothesis is that it must be testable and verifiable. Researchers should be able to design experiments or collect data to prove or disprove the hypothesis objectively. If a hypothesis cannot be tested or verified with empirical evidence, it has no scientific value. Testability ensures that the hypothesis remains grounded in reality and allows researchers to apply statistical tools, experiments, or observations to validate the proposed relationships or statements.

  • Simple and Clear

A good hypothesis must be simple, clear, and understandable. It should not be complex or vague, as this makes testing and interpretation difficult. The clarity of a hypothesis allows researchers and readers to grasp its meaning without confusion. It should specifically state the expected relationship between variables and avoid unnecessary technical jargon. A simple hypothesis makes the research process more organized and structured, leading to more reliable and meaningful results during analysis.

  • Specific and Focused

The nature of a hypothesis demands that it be specific and focused on a particular issue or problem. It should not be broad or cover unrelated aspects, which can dilute the research findings. Specificity helps researchers concentrate their efforts on one clear objective, design relevant research methods, and gather precise data. A focused hypothesis reduces ambiguity, minimizes errors, and improves the validity of the research results by maintaining a sharp direction throughout the study.

  • Consistent with Existing Knowledge

A hypothesis should align with the existing body of knowledge and theories unless it aims to challenge or expand them. It should logically fit into the current understanding of the subject to make sense scientifically. When a hypothesis is consistent with known facts, it gains credibility and relevance. Even when proposing something new, a hypothesis should acknowledge previous research and build upon it, rather than ignoring established evidence or scientific frameworks.

  • Objective and Neutral

A hypothesis must be objective and free from personal bias, emotions, or preconceived notions. It should be based on observable facts and logical reasoning rather than personal beliefs. Researchers must frame their hypotheses with neutrality to ensure that the research process remains fair and unbiased. Objectivity enhances the scientific value of the study and ensures that conclusions are drawn based on evidence rather than assumptions, preferences, or subjective interpretations.

  • Tentative and Provisional

A hypothesis is not a confirmed truth but a tentative statement awaiting validation through research. It is subject to change, modification, or rejection based on the findings. Researchers must remain open-minded and willing to revise the hypothesis if new evidence contradicts it. This provisional nature is crucial for the progress of scientific inquiry, as it encourages continuous testing, exploration, and refinement of ideas instead of blindly accepting assumptions.

  • Relational Nature

Hypotheses often establish relationships between two or more variables. They state how one variable may affect, influence, or be associated with another. This relational nature forms the backbone of experimental and correlational research designs. Understanding these relationships helps researchers explain causes, predict effects, and identify patterns within their study areas. Clearly stated relationships in hypotheses also facilitate the application of statistical tests and the interpretation of research findings effectively.

Significance of Hypothesis:

  • Guides the Research Process

The hypothesis acts as a roadmap for the researcher, providing clear direction and focus. It helps define what needs to be studied, which variables to observe, and what methods to apply. Without a hypothesis, research would be unguided and scattered. By offering a structured path, it ensures that the research efforts are purposeful and systematically organized toward achieving meaningful outcomes.

  • Defines the Focus of Study

A hypothesis narrows the scope of the study by specifying exactly what the researcher aims to investigate. It identifies key variables and their expected relationships, preventing unnecessary data collection. This concentration saves time and resources while allowing for more detailed analysis. A focused study helps in maintaining clarity throughout the research process and results in stronger, more convincing conclusions based on targeted inquiry.

  • Establishes Relationships Between Variables

A hypothesis highlights the potential relationships between two or more variables. It outlines whether variables move together, influence each other, or remain independent. Establishing these relationships is essential for explaining complex phenomena. Through hypothesis testing, researchers can confirm or reject assumed connections, leading to deeper understanding, better theories, and stronger predictive capabilities in both scientific and business research contexts.

  • Helps in Developing Theories

Hypotheses contribute significantly to theory building. When a hypothesis is repeatedly tested and supported by empirical evidence, it can help form new theories or refine existing ones. Theories built on tested hypotheses have greater scientific value and can guide future research and practice. Thus, hypotheses are not just for individual studies; they play a critical role in expanding the broader knowledge base of a discipline.

  • Facilitates the Testing of Concepts

Concepts and assumptions need validation before they can be widely accepted. A hypothesis facilitates this validation by providing a mechanism for empirical testing. It helps researchers design experiments or surveys specifically aimed at confirming or disproving a particular idea. This ensures that concepts do not remain speculative but are subjected to rigorous scientific scrutiny, enhancing the reliability and acceptance of research findings.

  • Enhances Objectivity in Research

Having a well-defined hypothesis enhances objectivity by setting specific criteria that research must meet. Researchers approach data collection and analysis with a neutral mindset focused on proving or disproving the hypothesis. This objectivity minimizes the influence of personal biases or preconceived notions, promoting fair and unbiased research results. In this way, hypotheses help maintain the scientific integrity of research projects.

  • Assists in Decision Making

In applied fields like business and healthcare, hypotheses help decision-makers by providing data-driven insights. By testing hypotheses about consumer behavior, product performance, or treatment outcomes, organizations and professionals can make informed decisions. This reduces risks and improves strategic planning. A hypothesis, therefore, transforms vague assumptions into evidence-based conclusions that directly impact policies, operations, and practices.

  • Saves Time and Resources

By clearly defining what needs to be studied, a hypothesis prevents researchers from wasting time and resources on irrelevant data. It limits the research to specific objectives and focuses efforts on gathering meaningful, actionable information. Efficient use of resources is critical in both academic and professional research settings, making a well-structured hypothesis an essential tool for maximizing productivity and effectiveness.

Null Hypothesis:

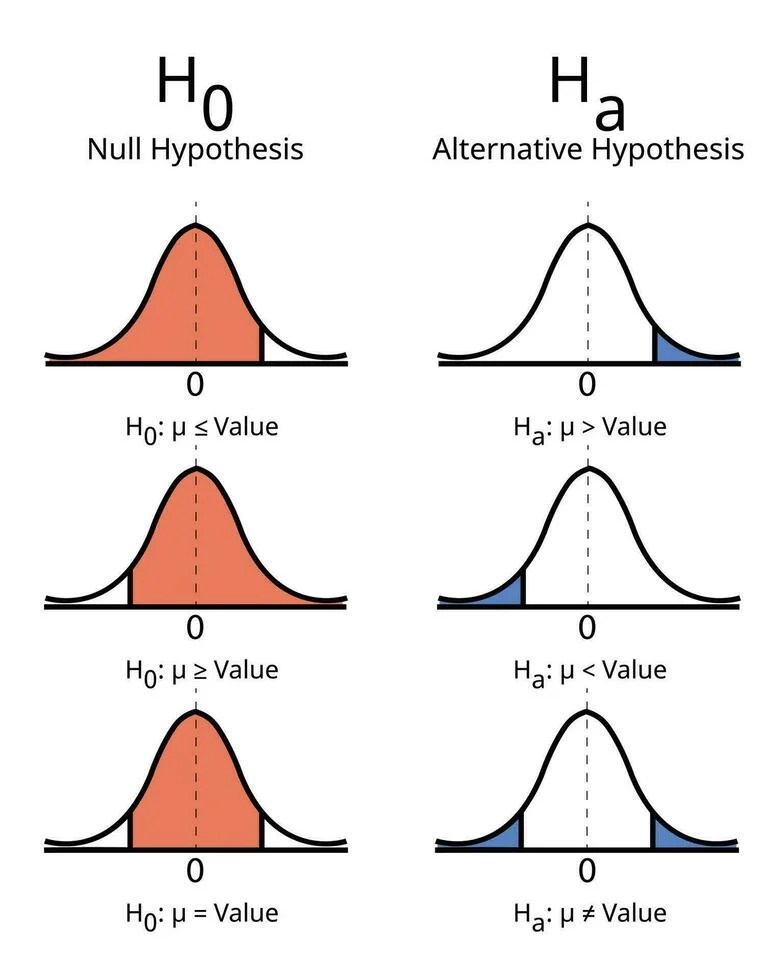
The null hypothesis (H₀) is a fundamental concept in statistical testing that proposes no significant relationship or difference exists between variables being studied. It serves as the default position that researchers aim to test against, representing the assumption that any observed effects are due to random chance rather than systematic influences.

In experimental design, the null hypothesis typically states there is:

  • No difference between groups

  • No association between variables

  • No effect of a treatment/intervention

For example, in testing a new drug’s efficacy, H₀ would state “the drug has no effect on symptom reduction compared to placebo.” Researchers then collect data to determine whether sufficient evidence exists to reject this null position in favor of the alternative hypothesis (H₁), which proposes an actual effect exists.

Statistical tests calculate the probability (p-value) of obtaining the observed results if H₀ were true. When this probability falls below a predetermined significance level (usually p < 0.05), researchers reject H₀. Importantly, failing to reject H₀ doesn’t prove its truth – it simply indicates insufficient evidence against it. The null hypothesis framework provides objective criteria for making inferences while controlling for Type I errors (false positives).

Alternative Hypothesis:

The alternative hypothesis represents the researcher’s actual prediction about a relationship between variables, contrasting with the null hypothesis. It states that observed effects are real and not due to random chance, proposing either:

  1. A significant difference between groups

  2. A measurable association between variables

  3. A true effect of an intervention

Unlike the null hypothesis’s conservative stance, the alternative hypothesis embodies the research’s theoretical expectations. In a clinical trial, while H₀ states “Drug X has no effect,” H₁ might claim “Drug X reduces symptoms by at least 20%.”

Alternative hypotheses can be:

  • Directional (one-tailed): Predicting the specific nature of an effect (e.g., “Group A will score higher than Group B”)

  • Non-directional (two-tailed): Simply stating a difference exists without specifying direction

Statistical testing doesn’t directly prove H₁; rather, it assesses whether evidence sufficiently contradicts H₀ to support the alternative. When results show statistical significance (typically p < 0.05), we reject H₀ in favor of H₁.

The alternative hypothesis drives research design by determining appropriate statistical tests, required sample sizes, and measurement precision. It must be formulated before data collection to prevent post-hoc reasoning. Well-constructed alternative hypotheses are testable, falsifiable, and grounded in theoretical frameworks, providing the foundation for meaningful scientific conclusions.

Sampling Techniques / Methods (Probability and Non-Probability Sampling Techniques) and Sampling Tools

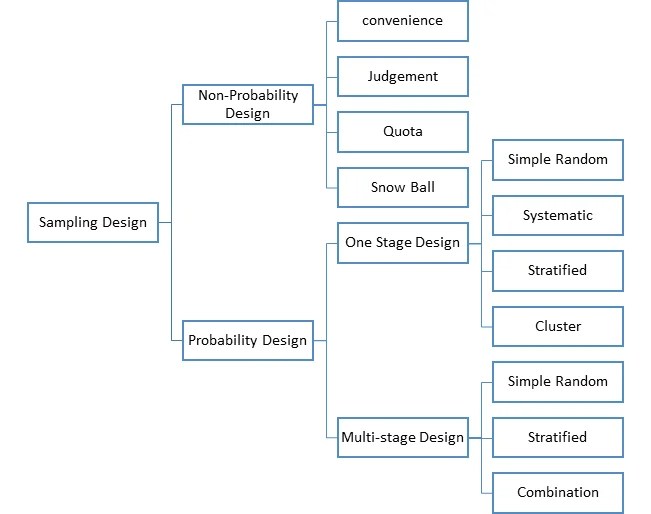
Sampling Techniques refer to the methods used to select individuals, items, or data points from a larger population for research purposes. These techniques ensure that the sample accurately represents the entire population, allowing for valid and reliable conclusions. Sampling techniques are broadly classified into two categories: probability sampling (where every element has an equal chance of being selected) and non-probability sampling (where selection is based on researcher judgment or convenience). Common methods include random sampling, stratified sampling, cluster sampling, convenience sampling, and purposive sampling. Choosing the right sampling technique is crucial because it impacts the quality, accuracy, and generalizability of the research findings. Proper sampling reduces bias and increases research credibility.

1. Probability Sampling Techniques

Probability sampling techniques are methods where every member of the population has a known and equal chance of being selected for the sample. These techniques aim to eliminate selection bias and ensure that the sample is truly representative of the entire population. Common types of probability sampling include simple random sampling, systematic sampling, stratified sampling, and cluster sampling. Researchers often prefer probability sampling because it allows the use of statistical methods to estimate population parameters and test hypotheses accurately. This approach enhances the validity, reliability, and generalizability of research findings, making it fundamental in scientific studies and decision-making processes.

Types of Probability Sampling Techniques

  • Simple Random Sampling

Every population member has an equal, independent chance of selection, typically using random number generators or lotteries. This method eliminates selection bias and ensures representativeness, making it ideal for homogeneous populations. However, it requires a complete sampling frame and may miss small subgroups. Despite its simplicity, large sample sizes are often needed for precision. It’s widely used in surveys and experimental research where unbiased representation is critical.

  • Stratified Random Sampling

The population is divided into homogeneous subgroups (strata), and random samples are drawn from each. This ensures representation of key characteristics (e.g., age, gender). It improves precision compared to simple random sampling, especially for heterogeneous populations. Proportionate stratification maintains population ratios, while disproportionate stratification may oversample rare groups. This method is costlier but valuable when subgroup comparisons are needed, such as in clinical or sociological studies.

  • Systematic Sampling

A fixed interval (*k*) is used to select samples from an ordered population list (e.g., every 10th person). The starting point is randomly chosen. This method is simpler than random sampling and ensures even coverage. However, if the list has hidden patterns, bias may occur. It’s efficient for large populations, like quality control in manufacturing or voter surveys, but requires caution to avoid periodicity-related distortions.

  • Cluster Sampling

The population is divided into clusters (e.g., schools, neighborhoods), and entire clusters are randomly selected for study. This reduces logistical costs, especially for geographically dispersed groups. However, clusters may lack internal diversity, increasing sampling error. Two-stage cluster sampling (randomly selecting subjects within chosen clusters) improves accuracy. It’s practical for national health surveys or educational research where individual access is challenging.

  • Multistage Sampling

A hybrid approach combining multiple probability methods (e.g., clustering followed by stratification). Large clusters are selected first, then subdivided for further random sampling. This balances cost and precision, making it useful for large-scale studies like census data collection or market research. While flexible, it requires careful design to minimize cumulative errors and maintain representativeness across stages.

2. Non-Probability Sampling Techniques

Non-probability Sampling refers to research methods where samples are selected through subjective criteria rather than random selection, meaning not all population members have an equal chance of participation. These techniques are used when probability sampling is impractical due to time, cost, or population constraints. Common approaches include convenience sampling (easily accessible subjects), purposive sampling (targeted selection of specific characteristics), snowball sampling (participant referrals), and quota sampling (pre-set subgroup representation). While these methods enable faster, cheaper data collection in exploratory or qualitative studies, they carry higher risk of bias and limit result generalizability to broader populations. Researchers employ them when prioritizing practicality over statistical representativeness.

Types of Non-Probability Sampling Techniques

  • Convenience Sampling

Researchers select participants who are most easily accessible, such as students in a classroom or shoppers at a mall. This method is quick, inexpensive, and requires minimal planning, making it ideal for preliminary research. However, results suffer from significant bias since the sample may not represent the target population. Despite limitations, convenience sampling is widely used in pilot studies, exploratory research, and when time/resources are constrained.

  • Purposive (Judgmental) Sampling

Researchers deliberately select specific individuals who meet predefined criteria relevant to the study. This technique is valuable when studying unique populations or specialized topics requiring expert knowledge. While it allows for targeted data collection, the subjective selection process introduces researcher bias. Purposive sampling is commonly used in qualitative research, case studies, and when investigating rare phenomena where random sampling isn’t feasible.

  • Snowball Sampling

Existing study participants recruit future subjects from their acquaintances, creating a chain referral process. This method is particularly useful for reaching hidden or hard-to-access populations like marginalized communities. While effective for sensitive topics, the sample may become homogeneous as participants share similar networks. Snowball sampling is frequently employed in sociological research, studies of illegal behaviors, and when investigating stigmatized conditions.

  • Quota Sampling

Researchers divide the population into subgroups and non-randomly select participants until predetermined quotas are filled. This ensures representation across key characteristics but lacks the randomness of stratified sampling. Quota sampling is more structured than convenience sampling yet still prone to selection bias. Market researchers often use this method when they need quick, cost-effective results that approximate population demographics.

  • Self-Selection Sampling

Individuals voluntarily choose to participate, typically by responding to open invitations or surveys. This approach yields large sample sizes easily but suffers from volunteer bias, as participants may differ significantly from non-respondents. Common in online surveys and call-in opinion polls, self-selection provides accessible data though results should be interpreted cautiously due to inherent representation issues.

Key differences between Probability and Non-Probability Sampling

Aspect Probability Sampling Non-Probability Sampling
Selection Basis Random Subjective
Bias Risk Low High
Representativeness High Low
Generalizability Strong Limited
Cost High Low
Time Required Long Short
Complexity High Low
Population Knowledge Required Optional
Error Control Measurable Unmeasurable
Use Cases Quantitative Qualitative
Statistical Tests Applicable Limited
Sample Frame Essential Flexible
Precision High Variable
Research Stage Confirmatory Exploratory
Participant Access Challenging Easy

Sampling Tools

Sampling tools are the techniques, procedures, or instruments used by researchers to select a suitable sample from a larger population. They help researchers identify participants systematically and ensure that the selected sample is appropriate for the research objectives. Common sampling tools and techniques include random number tables, computer-generated random selection, sampling frames, questionnaires for participant screening, and selection criteria. These tools help reduce selection bias and improve the reliability and usefulness of research findings.

Tools of Sampling

1. Sampling Frame

A sampling frame is a complete or organized list of members of the population from which the researcher selects a sample. It may contain names, identification numbers, addresses, or other relevant information. A proper sampling frame helps researchers identify eligible participants and apply sampling techniques systematically. It is particularly important in probability sampling because every suitable member should have an appropriate opportunity for selection. An accurate sampling frame reduces selection errors.

2. Random Number Table

A random number table is a traditional tool used to select participants randomly from a population. Each member is assigned a unique number, and numbers are selected from a table according to a predetermined procedure. Since selection is based on chance, personal judgment is minimized. Random number tables are useful for simple random sampling and help researchers reduce selection bias while ensuring that eligible population members have an opportunity to be included.

3. Computer Random Selection

Computer random selection uses software or digital applications to choose participants from a population. Researchers enter the sampling frame and specify the required sample size, after which the system generates random selections. This tool is faster and more convenient than manual random selection, particularly for large populations. Computer-based selection can improve accuracy and reduce human error. It is commonly used in quantitative research involving probability sampling techniques.

4. Lottery Method

The lottery method is a simple technique for selecting a random sample. Each member of the population is assigned a number or written on an identical slip, and the required number of slips is selected randomly. Every member has an equal chance of being chosen. This method is easy to understand and inexpensive to use, especially for small populations. However, it becomes difficult to manage when the population size is very large.

5. Sampling Interval

Sampling interval is a tool used mainly in systematic sampling to determine the regular gap between selected population members. It is usually calculated by dividing the population size by the desired sample size. After selecting a suitable starting point, every specified interval is chosen from the sampling frame. This approach provides an organized method of selection and can be easier to implement than simple random sampling when a complete population list is available.

6. Selection Criteria

Selection criteria are specific conditions used to determine who can participate in a research study. Researchers may establish inclusion and exclusion requirements based on the research objectives, population characteristics, or study design. Clear criteria ensure that only relevant participants are selected. They also improve consistency in sampling and reduce inappropriate selections. Well-defined criteria help researchers obtain information from participants who are directly related to the research problem.

7. Screening Questionnaire

A screening questionnaire can be used to identify participants who meet the requirements of a research study. It contains preliminary questions related to characteristics, experiences, eligibility, or other research requirements. Researchers review responses and select participants who satisfy the predetermined conditions. Screening questionnaires are particularly useful when the target population has specific characteristics. They help improve the relevance of the sample and prevent unsuitable participants from being included.

8. Sample Size Calculator

A sample size calculator is a statistical tool used to determine the appropriate number of participants required for a study. It may consider factors such as population size, confidence level, margin of error, and expected variability. Selecting an appropriate sample size helps balance accuracy and available resources. A sample that is too small may produce unreliable findings, while an unnecessarily large sample can increase time, cost, and effort.

Research, Introduction, Meaning, Definition, Objective, Purpose, Types, Importance and Challenges

Research is a systematic and organized process of collecting, analyzing, and interpreting information to increase understanding of a topic or issue. It aims to discover new facts, verify existing knowledge, or solve specific problems through careful investigation. Research can be theoretical or applied, and it involves forming hypotheses, gathering data, and drawing conclusions. It is essential in academic, scientific, and business fields to make informed decisions and improve practices. A well-conducted research study follows a structured methodology to ensure reliability and validity. Overall, research is a tool for expanding knowledge and contributing to the development of society and industries.

Definition of Research

  • Clifford Woody

Research is a careful inquiry or examination to discover new facts or verify old ones.

  • Creswell

Research is a process of steps used to collect and analyze information to increase our understanding of a topic.

  • Redman and Mory

Research is a systematized effort to gain new knowledge.

  • Kerlinger

Research is a systematic, controlled, empirical, and critical investigation of hypothetical propositions.

  • Lundberg

Research is a systematic activity directed towards the discovery and development of an organized body of knowledge.

Objective of Research

  • To Gain Familiarity with a Phenomenon

One major objective of research is to explore and understand a phenomenon or concept more clearly. This is often done through exploratory research, especially when little prior knowledge exists. It helps researchers gain insights into new topics, identify trends, and lay the groundwork for future studies. By becoming familiar with unfamiliar issues, researchers can form better hypotheses and research questions. This foundational understanding is critical for developing more in-depth research and creating meaningful contributions to academic and professional fields.

  • To Describe a Phenomenon Accurately

Descriptive research aims to systematically and precisely describe the characteristics of a subject, event, or population. Whether it’s human behavior, market trends, or institutional processes, this type of research collects detailed information to create an accurate picture. The objective is not to determine cause-and-effect but to define “what is” in a clear and factual manner. Such descriptions help researchers, practitioners, and policymakers understand the current state of affairs and serve as a reference point for comparing future changes.

  • To Establish Cause-and-Effect Relationships

Causal or explanatory research seeks to identify and analyze relationships between variables, often using experiments or observational studies. The objective is to determine how and why certain phenomena occur. For instance, a business might study the impact of advertising on sales. Establishing cause-and-effect allows researchers to predict outcomes and design effective interventions. This type of research is essential in fields like science, economics, and medicine, where understanding the effects of one factor on another can lead to critical discoveries and solutions.

  • To Test Hypotheses

Another key objective of research is hypothesis testing, where assumptions or predictions made before a study are examined for accuracy. Researchers design experiments or surveys to gather data that supports or refutes their hypotheses. The goal is to provide empirical evidence for or against theoretical statements. This process sharpens theories, confirms findings, and promotes scientific accuracy. Testing hypotheses is particularly important in quantitative research, as it relies on statistical techniques to validate conclusions and ensure objectivity.

  • To Develop New Theories and Concepts

Research often leads to the creation or refinement of theories and models that explain how the world works. The objective here is to go beyond existing knowledge and offer new perspectives or conceptual frameworks. Through in-depth analysis, researchers can challenge outdated views and propose innovative explanations. These new theories guide future research, inform policy, and influence practice across disciplines. In academic fields, theoretical research forms the basis for scholarly progress and intellectual advancement.

  • To Find Solutions to Practical Problems

Applied research is conducted with the specific objective of solving real-world problems. Whether it’s improving product design, enhancing public health, or increasing workplace efficiency, the goal is to apply scientific methods to practical challenges. This kind of research is widely used in industries, education, and government. It not only addresses current issues but also anticipates future needs. By developing effective strategies and solutions, applied research makes a direct contribution to societal well-being and economic development.

  • To Predict Future Trends

Research aims to forecast what may happen in the future based on current and past data. Predictive research uses statistical tools and modeling techniques to identify patterns and trends that inform future outcomes. For example, businesses use market research to predict consumer behavior, and climate scientists use data to forecast environmental changes. These predictions guide planning and strategic decisions. Accurate forecasting is essential for minimizing risk, improving preparedness, and making proactive decisions in dynamic environments.

  • To Enhance Understanding and Clarify Doubts

Research helps deepen our understanding of complex topics and clarifies uncertainties that may exist in previous studies or beliefs. By investigating issues from multiple angles, using various methods, and verifying results, research ensures greater clarity and accuracy. This objective is crucial in academia and science, where incomplete or conflicting information often leads to confusion. Ongoing research contributes to refinement, resolution of debates, and filling knowledge gaps, ensuring a more complete and reliable understanding of any subject.

Purpose of Research

  • Discovery of New Knowledge

One of the primary purposes of research is to discover new facts, ideas, and knowledge. Research helps in expanding the existing pool of information by exploring unknown areas and generating fresh insights. Through systematic investigation, researchers identify new relationships, concepts, and principles that were previously unexplored. This contributes to the growth of various disciplines such as science, management, economics, and social sciences. Discovery-oriented research lays the foundation for innovation, development, and further academic inquiry in different fields of study.

  • Verification of Existing Knowledge

Research is conducted to test and verify the validity of existing theories, laws, and concepts. Many ideas accepted over time require re-examination due to changing conditions, new evidence, or technological advancements. Research helps confirm whether earlier findings are still relevant and accurate. This process strengthens the reliability of knowledge by removing errors, misconceptions, and outdated assumptions. Verification through research ensures that decisions, policies, and practices are based on dependable and scientifically tested information.

  • Solution to Practical Problems

Another important purpose of research is to provide solutions to real-life problems faced by individuals, organizations, industries, and society. Applied research focuses on identifying causes of problems and suggesting effective remedies. In business, research helps solve issues related to production, marketing, finance, and human resources. In social sciences, it addresses problems like poverty, unemployment, and health. Thus, research acts as a tool for problem-solving and practical decision-making.

  • Development of Theories and Concepts

Research helps in developing new theories, models, and conceptual frameworks. By analyzing data and observing patterns, researchers formulate generalizations and principles that explain phenomena. These theories provide a systematic understanding of relationships among variables and guide future research. Theory-building research enhances academic depth and strengthens subject foundations. It also helps practitioners apply theoretical knowledge in practical situations, thereby bridging the gap between theory and practice in various disciplines.

  • Prediction and Forecasting

Research plays a significant role in predicting future trends and outcomes. By studying past and present data, researchers can forecast changes in markets, consumer behavior, population growth, and economic conditions. Such predictions help organizations and governments plan for the future and reduce uncertainty. Forecasting through research supports strategic planning, risk management, and policy formulation. Accurate predictions enable better preparedness for challenges and opportunities that may arise in the future.

  • Improvement in Decision Making

One of the key purposes of research is to support sound and rational decision-making. Research provides relevant, accurate, and timely information required for making informed choices. In business and management, research reduces guesswork and reliance on intuition. Decisions related to investment, product development, and policy implementation become more effective when backed by research findings. Thus, research improves the quality of decisions and enhances efficiency and effectiveness in achieving objectives.

  • Advancement of Social and Economic Development

Research contributes significantly to social and economic progress. It helps identify social issues, evaluate government programs, and suggest improvements in public policies. Economic research aids in understanding growth patterns, inflation, employment, and income distribution. Through research, innovative solutions are developed to improve living standards and promote sustainable development. Hence, research supports national development by providing a scientific basis for planning, reforms, and welfare initiatives.

  • Enhancement of Knowledge and Learning

Research promotes intellectual growth and continuous learning. It develops analytical thinking, creativity, and problem-solving abilities among researchers and students. Through research, individuals gain deeper understanding of subjects and develop a scientific attitude. It encourages questioning, exploration, and logical reasoning. This purpose is especially important in education, where research-based learning improves academic quality and contributes to personal and professional development.

Types of Research

1. Basic Research

Basic research, also known as pure or fundamental research, is conducted to expand existing knowledge without focusing on immediate practical application. Its main objective is to develop theories, principles, and generalizations. This type of research helps in understanding fundamental aspects of a subject and provides a foundation for applied research. Although it may not offer direct solutions, basic research is essential for long-term academic growth and scientific advancement.

2. Applied Research

Applied research is undertaken to solve specific, practical problems faced by individuals, organizations, or society. It focuses on applying theoretical knowledge to real-life situations. This type of research is common in fields like business, management, medicine, and engineering. The findings of applied research are directly useful for decision-making and problem-solving. It helps improve products, processes, and services by providing workable solutions.

3. Descriptive Research

Descriptive research aims to describe the characteristics of a population, situation, or phenomenon accurately. It does not control variables but observes and reports conditions as they exist. Surveys, questionnaires, and observational methods are commonly used. This type of research helps in understanding “what is happening” rather than “why it happens.” Descriptive research is widely used in social sciences, marketing, and business studies.

4. Analytical Research

Analytical research involves the use of existing data to analyze and evaluate relationships among variables. The researcher critically examines facts and information to draw conclusions. Unlike descriptive research, analytical research focuses on “why” and “how” aspects. It requires logical reasoning and statistical tools. This type of research is useful in policy analysis, financial studies, and economic research to understand cause-and-effect relationships.

5. Exploratory Research

Exploratory research is conducted when a problem is not clearly defined or when little information is available. Its purpose is to gain initial insights and understanding of the problem. Methods such as interviews, focus groups, and literature reviews are commonly used. Exploratory research helps in formulating hypotheses and identifying variables for further study. It provides direction for more detailed and structured research.

6. Qualitative Research

Qualitative research focuses on understanding human behavior, opinions, and experiences in a non-numerical form. It uses methods like interviews, case studies, and observations. This type of research emphasizes depth rather than quantity of data. Qualitative research helps in exploring attitudes, motivations, and perceptions. It is widely used in social sciences, psychology, and management to gain detailed insights.

7. Quantitative Research

Quantitative research deals with numerical data and statistical analysis. It aims to quantify variables and examine relationships using structured tools like surveys and experiments. This type of research provides measurable and objective results. Quantitative research is useful for testing hypotheses and making generalizations. It is commonly used in business, economics, and scientific studies where precision and accuracy are required.

8. Conceptual and Empirical Research

Conceptual research is based on abstract ideas, theories, and concepts. It involves logical reasoning and theoretical analysis without relying on observation. Empirical research, on the other hand, is based on actual observations and experiments. It relies on data collection and evidence. Both types are important, as conceptual research builds theories, while empirical research tests and validates them in real-world conditions.

Importance of Research

  • Expansion of Knowledge

Research plays a vital role in expanding human knowledge. It helps us understand concepts, theories, and facts in a deeper and more meaningful way. Through systematic investigation, research uncovers hidden truths and broadens the scope of what is already known. This continuous process of discovery is essential in education, science, and innovation. Without research, the development of new ideas, improvements in technology, and advancements in various fields would come to a standstill.

  • Problem Solving

One of the main purposes of research is to find solutions to problems. In both academic and practical settings, research helps identify the root causes of issues and suggests possible remedies. Whether it’s a social, economic, scientific, or business problem, research provides the tools and frameworks to analyze the situation effectively. It allows decision-makers to make evidence-based choices and implement strategies that are backed by data and analysis, leading to more successful outcomes.

  • Informed Decision Making

Research enables individuals, organizations, and governments to make informed decisions. By analyzing data and studying trends, research provides a factual basis for choosing between alternatives. In business, it helps managers decide on product development, marketing strategies, and investment plans. In public policy, it helps lawmakers craft laws that address real needs. This reduces the risk of failure and ensures that decisions are effective, efficient, and aligned with actual conditions and demands.

  • Economic Development

Research is essential for economic growth and development. It leads to the creation of new products, services, and technologies, which drive industry and generate employment. By improving productivity, reducing costs, and increasing competitiveness, research directly contributes to the success of businesses and national economies. Additionally, research in areas like agriculture, health, and education ensures sustainable development by solving real-world problems and improving the quality of life for individuals and communities.

  • Improvement in Education

Research strengthens the education system by improving teaching methods, learning outcomes, and academic content. It helps educators understand student needs, evaluate curricula, and adopt innovative practices. Research also enables students and teachers to stay updated with the latest knowledge in their field, promoting lifelong learning. Educational research contributes to the development of better textbooks, e-learning tools, and inclusive teaching strategies that cater to diverse learning styles and backgrounds.

  • Policy Formulation

Government and institutional policies must be based on reliable data and analysis, which research provides. Whether in health, education, environment, or public safety, research ensures that policies are relevant, effective, and future-ready. It helps policymakers assess the potential impact of laws and regulations, avoiding guesswork and promoting social welfare. Evidence-based policies are more likely to gain public support and achieve their goals, ultimately benefiting the economy and society as a whole.

  • Innovation and Technology Advancement

Innovation thrives on research. From developing new medical treatments to designing smarter devices, research is the foundation of technological progress. Scientists and engineers rely on research to explore possibilities, test ideas, and turn concepts into real-world applications. Research also encourages creativity and collaboration across disciplines, pushing the boundaries of what’s possible. As technology rapidly evolves, research ensures that innovation continues to meet the needs of people and adapt to changing environments.

  • Social and Cultural Understanding

Research deepens our understanding of social and cultural dynamics. It helps explore human behavior, beliefs, traditions, and societal changes. Through research in fields like sociology, anthropology, and psychology, we gain insights into communities and cultures, fostering tolerance and mutual respect. This understanding is crucial in a globalized world where collaboration and coexistence are key. It also helps in addressing social issues like poverty, gender inequality, and discrimination with informed, data-backed strategies.

Challenges in Research

  • Problem Identification and Definition

One of the major challenges in research is identifying and clearly defining the research problem. An unclear or poorly framed problem leads to confusion and ineffective results. Researchers often face difficulty in narrowing down a broad topic into a specific and researchable problem. Lack of clarity affects objectives, hypothesis formulation, and methodology. Proper understanding of the problem is essential, as the entire research process depends on accurate problem identification and precise definition.

  • Availability of Reliable Data

Availability of accurate and reliable data is a significant challenge in research. Researchers may face incomplete, outdated, or inconsistent data sources. In some cases, data may not be accessible due to confidentiality or restrictions. Primary data collection can be costly and time-consuming, while secondary data may lack relevance. Poor quality data directly affects the validity and reliability of research findings, making conclusions less dependable.

  • Time Constraints

Time limitation is a common challenge faced by researchers, especially students and professionals. Research involves multiple stages such as literature review, data collection, analysis, and reporting, each requiring adequate time. Due to academic deadlines or organizational pressure, researchers may rush through processes, leading to errors and superficial analysis. Insufficient time affects depth, accuracy, and overall quality of research work.

  • Financial Constraints

Lack of adequate funds poses a major challenge in conducting research. Expenses related to data collection, fieldwork, surveys, software, and expert consultation can be high. Limited financial resources restrict sample size, research tools, and scope of the study. Due to budget constraints, researchers may compromise on quality and methodology, which negatively impacts the reliability and effectiveness of research outcomes.

  • Selection of Appropriate Research Methodology

Choosing the correct research methodology is often challenging. Researchers may struggle to select suitable research design, sampling techniques, and data collection methods. Incorrect methodology leads to biased results and invalid conclusions. Lack of experience or guidance further complicates this challenge. Proper alignment between research objectives and methodology is crucial to ensure meaningful and accurate findings.

  • Researcher Bias and Subjectivity

Researcher bias is a serious challenge that affects objectivity. Personal beliefs, assumptions, and expectations may influence data collection, interpretation, and conclusions. Bias can occur intentionally or unintentionally, leading to distorted results. Maintaining neutrality and using standardized tools is essential. Overcoming bias requires awareness, ethical conduct, and adherence to scientific principles throughout the research process.

  • Ethical Issues in Research

Ethical challenges are common in research involving human subjects. Issues such as informed consent, privacy, confidentiality, and data misuse must be carefully handled. Researchers may face difficulty in balancing research objectives with ethical responsibilities. Failure to follow ethical standards can lead to legal consequences and loss of credibility. Ethical compliance is essential for responsible and trustworthy research.

  • Data Analysis and Interpretation

Analyzing and interpreting data accurately is a complex challenge in research. Researchers may lack technical knowledge of statistical tools and software. Misinterpretation of data can lead to incorrect conclusions. Large volumes of data increase complexity and chances of error. Proper training, use of appropriate analytical techniques, and careful interpretation are necessary to ensure valid and meaningful research results.

Sampling and Sampling Distribution

Sample design is the framework, or road map, that serves as the basis for the selection of a survey sample and affects many other important aspects of a survey as well. In a broad context, survey researchers are interested in obtaining some type of information through a survey for some population, or universe, of interest. One must define a sampling frame that represents the population of interest, from which a sample is to be drawn. The sampling frame may be identical to the population, or it may be only part of it and is therefore subject to some under coverage, or it may have an indirect relationship to the population.

Sampling is the process of selecting a subset of individuals, items, or observations from a larger population to analyze and draw conclusions about the entire group. It is essential in statistics when studying the entire population is impractical, time-consuming, or costly. Sampling can be done using various methods, such as random, stratified, cluster, or systematic sampling. The main objectives of sampling are to ensure representativeness, reduce costs, and provide timely insights. Proper sampling techniques enhance the reliability and validity of statistical analysis and decision-making processes.

Steps in Sample Design

While developing a sampling design, the researcher must pay attention to the following points:

  • Type of Universe:

The first step in developing any sample design is to clearly define the set of objects, technically called the Universe, to be studied. The universe can be finite or infinite. In finite universe the number of items is certain, but in case of an infinite universe the number of items is infinite, i.e., we cannot have any idea about the total number of items. The population of a city, the number of workers in a factory and the like are examples of finite universes, whereas the number of stars in the sky, listeners of a specific radio programme, throwing of a dice etc. are examples of infinite universes.

  • Sampling unit:

A decision has to be taken concerning a sampling unit before selecting sample. Sampling unit may be a geographical one such as state, district, village, etc., or a construction unit such as house, flat, etc., or it may be a social unit such as family, club, school, etc., or it may be an individual. The researcher will have to decide one or more of such units that he has to select for his study.

  • Source list:

It is also known as ‘sampling frame’ from which sample is to be drawn. It contains the names of all items of a universe (in case of finite universe only). If source list is not available, researcher has to prepare it. Such a list should be comprehensive, correct, reliable and appropriate. It is extremely important for the source list to be as representative of the population as possible.

  • Size of Sample:

This refers to the number of items to be selected from the universe to constitute a sample. This a major problem before a researcher. The size of sample should neither be excessively large, nor too small. It should be optimum. An optimum sample is one which fulfills the requirements of efficiency, representativeness, reliability and flexibility. While deciding the size of sample, researcher must determine the desired precision as also an acceptable confidence level for the estimate. The size of population variance needs to be considered as in case of larger variance usually a bigger sample is needed. The size of population must be kept in view for this also limits the sample size. The parameters of interest in a research study must be kept in view, while deciding the size of the sample. Costs too dictate the size of sample that we can draw. As such, budgetary constraint must invariably be taken into consideration when we decide the sample size.

  • Parameters of interest:

In determining the sample design, one must consider the question of the specific population parameters which are of interest. For instance, we may be interested in estimating the proportion of persons with some characteristic in the population, or we may be interested in knowing some average or the other measure concerning the population. There may also be important sub-groups in the population about whom we would like to make estimates. All this has a strong impact upon the sample design we would accept.

  • Budgetary constraint:

Cost considerations, from practical point of view, have a major impact upon decisions relating to not only the size of the sample but also to the type of sample. This fact can even lead to the use of a non-probability sample.

  • Sampling procedure:

Finally, the researcher must decide the type of sample he will use i.e., he must decide about the technique to be used in selecting the items for the sample. In fact, this technique or procedure stands for the sample design itself. There are several sample designs (explained in the pages that follow) out of which the researcher must choose one for his study. Obviously, he must select that design which, for a given sample size and for a given cost, has a smaller sampling error.

Types of Samples

  • Probability Sampling (Representative samples)

Probability samples are selected in such a way as to be representative of the population. They provide the most valid or credible results because they reflect the characteristics of the population from which they are selected (e.g., residents of a particular community, students at an elementary school, etc.). There are two types of probability samples: random and stratified.

  • Random Sample

The term random has a very precise meaning. Each individual in the population of interest has an equal likelihood of selection. This is a very strict meaning you can’t just collect responses on the street and have a random sample.

The assumption of an equal chance of selection means that sources such as a telephone book or voter registration lists are not adequate for providing a random sample of a community. In both these cases there will be a number of residents whose names are not listed. Telephone surveys get around this problem by random-digit dialling but that assumes that everyone in the population has a telephone. The key to random selection is that there is no bias involved in the selection of the sample. Any variation between the sample characteristics and the population characteristics is only a matter of chance.

  • Stratified Sample

A stratified sample is a mini-reproduction of the population. Before sampling, the population is divided into characteristics of importance for the research. For example, by gender, social class, education level, religion, etc. Then the population is randomly sampled within each category or stratum. If 38% of the population is college-educated, then 38% of the sample is randomly selected from the college-educated population.

Stratified samples are as good as or better than random samples, but they require fairly detailed advance knowledge of the population characteristics, and therefore are more difficult to construct.

  • Non-probability Samples (Non-representative samples)

As they are not truly representative, non-probability samples are less desirable than probability samples. However, a researcher may not be able to obtain a random or stratified sample, or it may be too expensive. A researcher may not care about generalizing to a larger population. The validity of non-probability samples can be increased by trying to approximate random selection, and by eliminating as many sources of bias as possible.

  • Quota Sample

The defining characteristic of a quota sample is that the researcher deliberately sets the proportions of levels or strata within the sample. This is generally done to insure the inclusion of a particular segment of the population. The proportions may or may not differ dramatically from the actual proportion in the population. The researcher sets a quota, independent of population characteristics.

Example: A researcher is interested in the attitudes of members of different religions towards the death penalty. In Iowa a random sample might miss Muslims (because there are not many in that state). To be sure of their inclusion, a researcher could set a quota of 3% Muslim for the sample. However, the sample will no longer be representative of the actual proportions in the population. This may limit generalizing to the state population. But the quota will guarantee that the views of Muslims are represented in the survey.

  • Purposive Sample

A purposive sample is a non-representative subset of some larger population, and is constructed to serve a very specific need or purpose. A researcher may have a specific group in mind, such as high level business executives. It may not be possible to specify the population they would not all be known, and access will be difficult. The researcher will attempt to zero in on the target group, interviewing whoever is available.

  • Convenience Sample

A convenience sample is a matter of taking what you can get. It is an accidental sample. Although selection may be unguided, it probably is not random, using the correct definition of everyone in the population having an equal chance of being selected. Volunteers would constitute a convenience sample.

Non-probability samples are limited with regard to generalization. Because they do not truly represent a population, we cannot make valid inferences about the larger group from which they are drawn. Validity can be increased by approximating random selection as much as possible, and making every attempt to avoid introducing bias into sample selection.

Sampling Distribution

Sampling Distribution is a statistical concept that describes the probability distribution of a given statistic (e.g., mean, variance, or proportion) derived from repeated random samples of a specific size taken from a population. It plays a crucial role in inferential statistics, providing the foundation for making predictions and drawing conclusions about a population based on sample data.

Concepts of Sampling Distribution

A sampling distribution is the distribution of a statistic (not raw data) over all possible samples of the same size from a population. Commonly used statistics include the sample mean (Xˉ\bar{X}), sample variance, and sample proportion.

Purpose:

It allows statisticians to estimate population parameters, test hypotheses, and calculate probabilities for statistical inference.

Shape and Characteristics:

    • The shape of the sampling distribution depends on the population distribution and the sample size.
    • For large sample sizes, the Central Limit Theorem states that the sampling distribution of the mean will be approximately normal, regardless of the population’s distribution.

Importance of Sampling Distribution

  • Facilitates Statistical Inference:

Sampling distributions are used to construct confidence intervals and perform hypothesis tests, helping to infer population characteristics.

  • Standard Error:

The standard deviation of the sampling distribution, called the standard error, quantifies the variability of the sample statistic. Smaller standard errors indicate more reliable estimates.

  • Links Population and Samples:

It provides a theoretical framework that connects sample statistics to population parameters.

Types of Sampling Distributions

  • Distribution of Sample Means:

Shows the distribution of means from all possible samples of a population.

  • Distribution of Sample Proportions:

Represents the proportion of a certain outcome in samples, used in binomial settings.

  • Distribution of Sample Variances:

Explains the variability in sample data.

Example

Consider a population of students’ test scores with a mean of 70 and a standard deviation of 10. If we repeatedly draw random samples of size 30 and calculate the sample mean, the distribution of those means forms the sampling distribution. This distribution will have a mean close to 70 and a reduced standard deviation (standard error).

Range and co-efficient of Range

The range is a measure of dispersion that represents the difference between the highest and lowest values in a dataset. It provides a simple way to understand the spread of data. While easy to calculate, the range is sensitive to outliers and does not provide information about the distribution of values between the extremes.

Range of a distribution gives a measure of the width (or the spread) of the data values of the corresponding random variable. For example, if there are two random variables X and Y such that X corresponds to the age of human beings and Y corresponds to the age of turtles, we know from our general knowledge that the variable corresponding to the age of turtles should be larger.

Since the average age of humans is 50-60 years, while that of turtles is about 150-200 years; the values taken by the random variable Y are indeed spread out from 0 to at least 250 and above; while those of X will have a smaller range. Thus, qualitatively you’ve already understood what the Range of a distribution means. The mathematical formula for the same is given as:

Range = L – S

where

L: The Largets/maximum value attained by the random variable under consideration

S: The smallest/minimum value.

Properties

  • The Range of a given distribution has the same units as the data points.
  • If a random variable is transformed into a new random variable by a change of scale and a shift of origin as:

Y = aX + b

where

Y: the new random variable

X: the original random variable

a,b: constants.

Then the ranges of X and Y can be related as:

RY = |a|RX

Clearly, the shift in origin doesn’t affect the shape of the distribution, and therefore its spread (or the width) remains unchanged. Only the scaling factor is important.

  • For a grouped class distribution, the Range is defined as the difference between the two extreme class boundaries.
  • A better measure of the spread of a distribution is the Coefficient of Range, given by:

Coefficient of Range (expressed as a percentage) = L – SL + S × 100

Clearly, we need to take the ratio between the Range and the total (combined) extent of the distribution. Besides, since it is a ratio, it is dimensionless, and can, therefore, one can use it to compare the spreads of two or more different distributions as well.

  • The range is an absolute measure of Dispersion of a distribution while the Coefficient of Range is a relative measure of dispersion.

Due to the consideration of only the end-points of a distribution, the Range never gives us any information about the shape of the distribution curve between the extreme points. Thus, we must move on to better measures of dispersion. One such quantity is Mean Deviation which is we are going to discuss now.

Interquartile range (IQR)

The interquartile range is the middle half of the data. To visualize it, think about the median value that splits the dataset in half. Similarly, you can divide the data into quarters. Statisticians refer to these quarters as quartiles and denote them from low to high as Q1, Q2, Q3, and Q4. The lowest quartile (Q1) contains the quarter of the dataset with the smallest values. The upper quartile (Q4) contains the quarter of the dataset with the highest values. The interquartile range is the middle half of the data that is in between the upper and lower quartiles. In other words, the interquartile range includes the 50% of data points that fall in Q2 and

The IQR is the red area in the graph below.

The interquartile range is a robust measure of variability in a similar manner that the median is a robust measure of central tendency. Neither measure is influenced dramatically by outliers because they don’t depend on every value. Additionally, the interquartile range is excellent for skewed distributions, just like the median. As you’ll learn, when you have a normal distribution, the standard deviation tells you the percentage of observations that fall specific distances from the mean. However, this doesn’t work for skewed distributions, and the IQR is a great alternative.

I’ve divided the dataset below into quartiles. The interquartile range (IQR) extends from the low end of Q2 to the upper limit of Q3. For this dataset, the range is 21 – 39.

error: Content is protected !!